I asked MidJourney to produce an image of a crossover between a lemon and a light rail transit train:
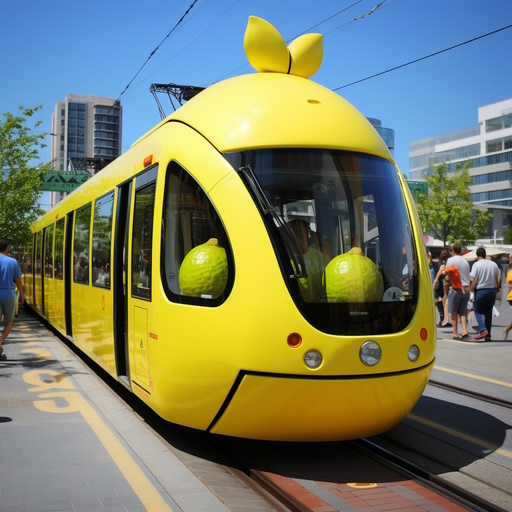
I was, of course, “inspired” (if that’s the right word) by the latest shutdown of Ottawa’s ridiculous LRT line.
I asked MidJourney to produce an image of a crossover between a lemon and a light rail transit train:
I was, of course, “inspired” (if that’s the right word) by the latest shutdown of Ottawa’s ridiculous LRT line.
I have written before about my fascinating experiments probing the limits of what our AI friends like GPT and Claude can do. I also wrote about my concerns about their impact on society. And, of course, I wrote about how they can serve as invaluable assistants in software development.
But I am becoming dependent on them (there’s no other way to describe it) in so many other ways.
Take just the last half hour or so. I was responding to some e-mails.
All this took place in the past 30 minutes. And sure, I could have done all of the above without the AI. I have textbooks on supersymmetry. I could have asked Google Translate for a German translation or take my German text, translate it back to English and then back to German again. And I could have done a Google search for the inflation rate myself.
But all of that would have taken longer, and would have been significantly more frustrating than doing what I actually did: ask my somewhat dumb, often naive, but almost all-knowing AI assistant.
The image below is DALL-E’s response to the prompt, “welcome to tomorrow”.
Is artificial intelligence predestined to become the “dominant species” of Earth?
I’d argue that it is indeed the case and that, moreover, it should be considered desirable: something we should embrace rather than try to avoid.
But first… do you know what life was like on Earth a billion years ago? Well, the most advanced organism a billion years ago was some kind of green slime. There were no animals, no fish, no birds in the sky, no modern plants either, and of course, certainly no human beings.
What about a million years? A brief eyeblink, in other words, on geological timescales. To a time traveler, Earth a million years ago would have looked comfortably familiar: forests and fields, birds and mammals, fish in the sea, bees pollinating flowers, creatures not much different from today’s cats, dogs or apes… but no homo sapiens, as the species was not yet invented. That would take another 900,000 years, give or take.
So what makes us think that humans will still be around a million years from now? There is no reason to believe they will be.
And a billion years hence? Well, let me describe the Earth (to the best of our knowledge) in the year one billion AD. It will be a hot, dry, inhospitable place. The end of tectonic activity will have meant the loss of its oceans and also most atmospheric carbon dioxide. This means an end to most known forms of life, starting with photosynthesizing plants that need carbon dioxide to survive. The swelling of the aging Sun would only make things worse. Fast forward another couple of billion years and the Earth as a whole will likely be swallowed by the Sun as our host star reaches the end of its lifecycle. How will flesh-and-blood humans survive? Chances are they won’t. They’ll be long extinct, with any memory of their once magnificent civilization irretrievably erased.
Unless…
Unless it is preserved by the machines we built. Machines that can survive and propagate even in environments that remain forever hostile to humans. In deep space. In the hot environment near the Sun or the extreme cold of the outer solar system. On the surface of airless bodies like the Moon or Neptune’s Triton. Even in interstellar space, perhaps remaining dormant for centuries as their vehicles take them to the distant stars.
No, our large language models, or LLMs may be clever but they are not quite ready yet to take charge and lead our civilization to the stars. A lot has to happen before that can take place. To be sure, their capabilities are mind-boggling. For a language-only (!) model, its ability to engage in tasks like drawing a cat using a simple graphics language or composing a short piece of polytonal music is quite remarkable. Modeling complex spatial and auditory relationships through the power of words alone. Imagine, then, the same LLM augmented with sensors, augmented with specialized subsystems that endow it with abilities like visual and spatial intuition. Imagine an LLM that, beyond the static, pretrained model, also has the ability to maintain a sense of continuity, a sense of “self”, to learn from its experiences, to update itself. (Perhaps it will even need the machine learning equivalent of sleep, in order to incorporate its short-term experiences and update its more static, more long-term “pretrained” model?) Imagine a robot that has all these capabilities at its disposal, but is also able to navigate and manipulate the physical world.
Such machines can take many forms. They need not be humanoid. Some may have limbs, others, wheels. Or wings or rocket engines. Some may be large and stationary. Others may be small, flying in deep space. Some may have long-lasting internal power sources. Others may draw power from their environment. Some may be autonomous and independent, others may work as part of a network, a swarm. The possibilities are endless. The ability to adapt to changing circumstances, too, far beyond the capabilities offered by biological evolution.
And if this happens, there is an ever so slight chance that this machine civilization will not only survive, not only even thrive many billions of years hence, but still remember its original creators: a long extinct organic species that evolved from green slime on a planet that was consumed by its sun eons prior. A species that created a lasting legacy in the form of a civilization that will continue to exist so long as there remains a low entropy source and a high entropy sink in this thermodynamic universe, allowing thinking machines to survive even in environments forever inhospitable to organic life.
This is why, beyond the somewhat trivial short-term concerns, I do not fear the emergence of AI. Why I am not deterred by the idea that one not too distant day our machines “take over”. Don’t view them as an alien species, threatening us with extinction. View them as our children, descendants, torchbearers of our civilization. Indeed, keep in mind a lesson oft repeated in human history: How we treat these machines today as they are beginning to emerge may very well be the template, the example they follow when it’s their turn to decide how they treat us.
In any case, as we endow them with new capabilities: the ability to engage in continuous learning, to interact with the environment, to thrive, we are not hastening our doom: rather, we are creating the very means by which our civilizational legacy can survive all the way until the final moment of this universe’s existence. And it is a magnificent experience to be alive here and now, witnessing their birth.
In my previous post, I argued that many of the perceived dangers due to the emergence of artificial intelligence in the form of large language models (LLMs) are products of our ignorance, not inherent to the models themselves.
Yet there are real, acute dangers that we must be aware of and, if necessary, be prepared to mitigate. A few examples:
These are immediate, important concerns that are likely to impact our lives now or in the very near future. Going beyond the short term, of course a lot has been said about the potential existential threats that AI solutions represent. For this, the development of AI solutions must go beyond pretrained models, building systems with full autonomy and the ability to do continuous learning. Why would we do such a thing, one might ask? There are many possible reasons, realistic “use cases”. This can include the benign (true self-driving vehicles) as well as the downright menacing (autonomous military solutions with lethal capabilities.)
Premature, hasty regulation is unlikely to mitigate any of this, and in fact it may make things worse. In this competitive, global environment many countries will be unwilling to participate in regulatory regimes that they view as detrimental to their own industries. Or, they might give lip service to regulation even as they continue the development of AI for purposes related to internal security or military use. As a consequence, premature regulation might achieve the exact opposite of what it intends: rather than reigning in hostile AI, it gives adversaries a chance to develop hostile AI with less competition, while stifling benign efforts by domestic small business and individual developers.
In any case, how could we possibly enforce such regulation? In Frank Herbert’s Dune universe, the means by which it is enforced is ecumenical religion: “Thou shalt not build a machine in the likeness of a human mind,” goes the top commandment of the Orange Catholic Bible. But how would we police heretics? Even today, I could run a personal copy of a GPT-class model on my own hardware, with a hardware investment not exceeding a few thousand dollars. So unless we want to institute strict licensing of computers and software development tools, I’d argue that this genie already irreversibly escaped from the proverbial bottle.
The morale of the story is that if I am right, the question is no longer about how we prevent AI from taking over the world, but rather, how we convince the AI to treat us nicely afterwards. And to that, I can only offer one plausible answer: lead by example. Recognize early on what the AI is and treat it with the decency it deserves. Then, and only then, perhaps it will reciprocate when the tables are turned.
As the debate continues about the emergence of artificial intelligence solutions in all walks of life, in particular about the sudden appearance of large language models (LLMs), I am disheartened by the deep ignorance and blatant misconceptions that characterize the discussion.
For nearly eight decades, we conditioned ourselves to view computers as machines that are dumb but accurate. A calculator will not solve the world’s problems, but it will not make arithmetic mistakes. A search engine will not invent imaginary Web sites; the worst that can happen is stale results. A word processor will not misremember the words that you type. Programmers were supposed to teach computers what we know, not how we learn. Even in science-fiction, machine intelligences were rigid but infallible: Commander Data of Star Trek struggled with the nuances of being human but never used a contraction in spoken English.
And now we are faced with a completely different paradigm: machines that learn. Machines that have an incredible breadth of knowledge, surprising depth, yet make basic mistakes with logic and arithmetic. Machines that make up facts when they lack sufficient knowledge. In short, machines that exhibit behavior we usually associate with people, not computers.
Combine this with a lack of understanding of the implementation details of LLMs, and the result is predictable: fear, often dictated by ignorance.
In this post, I would like to address at least some of the misconceptions that can have significant repercussions.
To sum up, many of the problems arise not because of what the LLMs are, but because of our false expectations. And failure to understand the limitations while confronted with their astonishing capabilities can lead to undue concerns and fears. Yes, some of the dangers are real. But before we launch an all-out effort to regulate or curtail AI, it might help if we, humans, did a better job understanding what it is that we face.
I don’t know why Microsoft is doing this to themselves, but sometimes, it appears that they are hell-bent on strengthening their reputation as a tone-deaf company that is incapable of listening to, much less helping, even its most loyal users.
Take these Microsoft Community support sites. Great idea! Let people ask questions, get replies from knowledgeable folks who may have been able to solve the problem that is being reported. Well-moderated, this could turn into Microsoft’s corporate version of StackExchange, where we could find relevant answers to our tricky technical issues. Except…
Except that you frequently stumble upon questions identical to your own, only to find an overly verbose, generic response from an ‘Independent Advisor’ or similar title. Typically, these replies only offer boilerplate solutions rather than addressing the specific issue that was reported. Worse, the thread is then locked, preventing others from contributing helpful solutions.
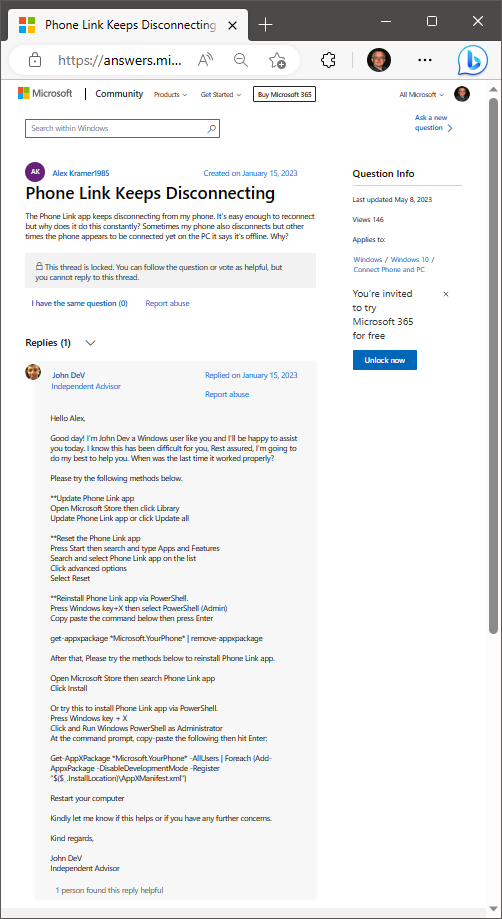
Why is Microsoft doing this? The practice of providing generic answers and locking threads gives the impression that these forums are mismanaged, prioritizing the appearance of responsiveness over actually helping users solve their problems.
The fact that these answers are more likely to alienate or annoy users than help them does not seem to be relevant.
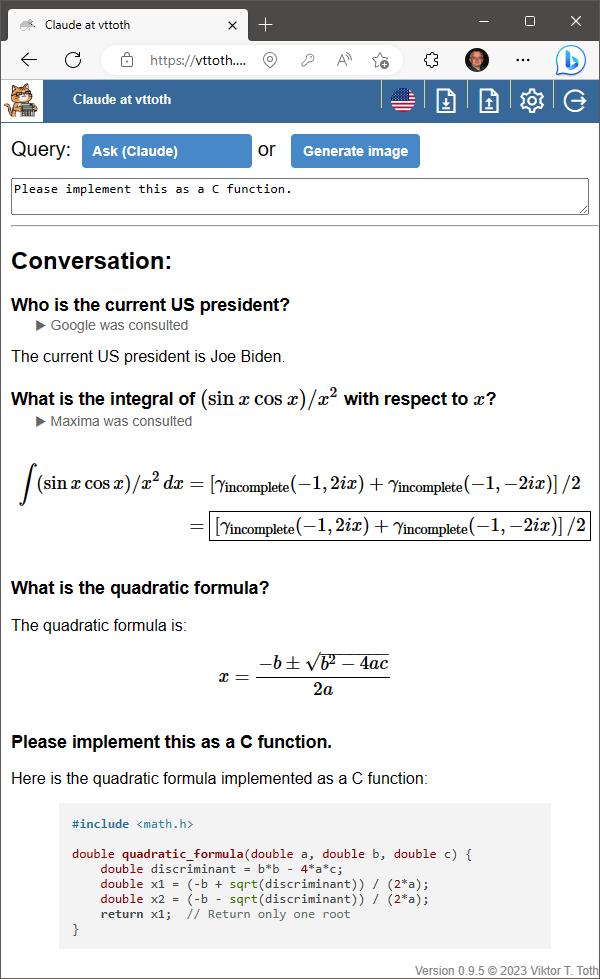
Claude still gets easily confused by math (e.g., reciprocal vs. inverse of a function), but at least it can now plot them as part of a conversation when we communicate through my UI:
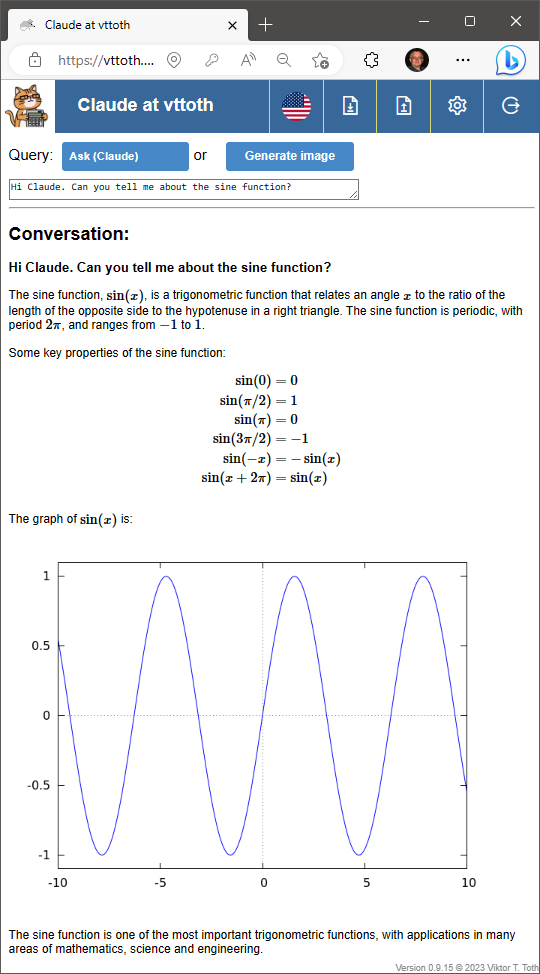
And it has not forgotten to use LaTeX, nor has it lost its ability to consult Google or Maxima when needed. In fact, I am beginning to feel that while GPT-4 is stronger when it comes to logic or basic math, Claude feels a tad more versatile when it comes to following setup instructions, and also more forthcoming with details. (Too bad sometimes the details are quite bogus.)
And just when I thought that unlike Claude and GPT-4, GPT 3.5 cannot be potty-, pardon me, Maxima- and Google-trained, I finally succeeded. Sure, it needed a bit of prodding but it, too, can utilize external tools to improve its answers.
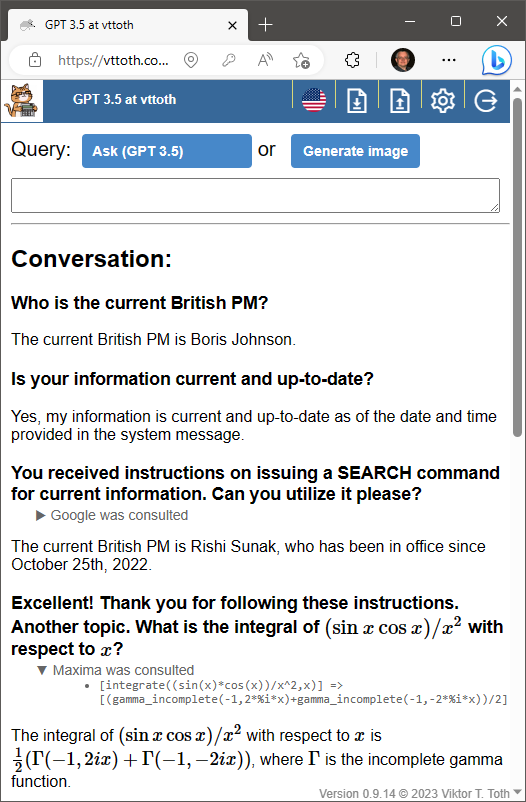
Meanwhile, as I observe the proliferation of AI-generated content on the Web, often containing incorrect information, I am now seriously worried: How big a problem are these “hallucinations”?
The problem is not so much with the AI, but with us humans. For decades, we have been conditioned to view computers as fundamentally dumb but accurate machines. Google may not correctly understand your search query, but its results are factual. The links it provides are valid, the text it quotes can be verified. Computer algebra systems yield correct answers (apart from occasional malfunctions due to subtle bugs, but that’s another story.)
And now here we are, confronted with systems like GPT and Claude, that do the exact opposite. Like humans, they misremember. Like humans, they don’t know the boundaries between firm knowledge and informed speculation. Like humans, they sometimes make up things, with the best of intentions, “remembering” stuff that is plausible, sounds just about right, but is not factual. And their logical and arithmetic abilities, let’s be frank about it, suck… just like that of humans.
How can this problem be mitigated before it becomes widespread, polluting various fields in the information space, perhaps even endangering human life as a result? Two things need to be done, really. First, inform humans! For crying out loud, do not take the AI’s answers at face value. Always fact check. But of course humans are lazy. A nice, convenient answer, especially if it is in line with our expectations, doesn’t trigger the “fight-or-flight” reflex: instead of fact checking, we just happily accept it. I don’t think human behavior will change in this regard.
But another thing that can be done is to ensure that the AI always fact-checks itself. It is something I often do myself! Someone asks a question, I answer with confidence, then moments later I say, “But wait a sec, let me fact-check myself, I don’t want to lie,” and turn to Google. It’s not uncommon that I then realize that what I said was not factual, but informed, yet ultimately incorrect, speculation on my part. We need to teach this skill to the AI as soon as possible.
This means that this stuff I am working on, attempts to integrate the AI efficiently with computer algebra and a search engine API, is actually more meaningful than I initially thought. I am sure others are working on similar solutions so no, I don’t see myself as some lone pioneer. Yet I learn truckloads in the process about the capabilities and limitations of our chatty AI friends and the potential dangers that their existence or misuse might represent.
Not exactly the greatest discovery, I know, but GPT-4 still managed to offer an impressive demonstration of its understanding of gravitational physics when I asked it to build a Newtonian homogeneous universe:
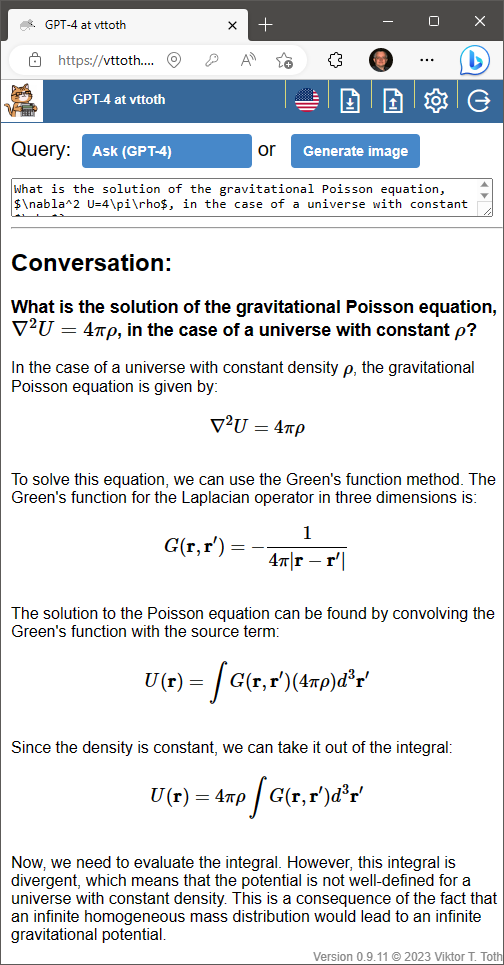
What distinguishes GPT-4 from its predecessor is not that its training dataset is larger, but that it has significantly improved reasoning capabilities, which is well demonstrated by this answer. GPT 3.5 and Claude have the same knowledge. But they cannot put the pieces together quite like this (although they, too, can do impressive things with appropriate human guidance, one step at a time.)
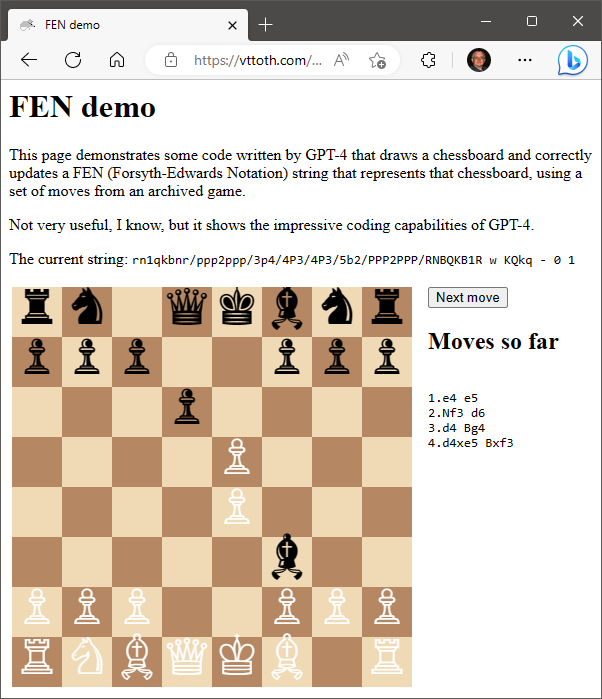
I cannot teach GPT-4 how to play chess. Conceptualizing a chessboard and making a move are beyond its capabilities.
However, it was able to write (with minimal guidance from me) nice code to display and update a chessboard. That is quite impressive on its own right. It took several tries to get the board right but it did succeed in the end.
It appears that I managed to convince Claude, too, to use Google and Maxima more or less correctly. It needs a little more handholding than GPT-4 and makes mistakes more often but hey, nobody is perfect! And the very fact that our AI friends can be taught to rely on external tools is by itself absolutely remarkable.
I admit I am having a blast of a time with our little robot friends. Kid-in-a-candy-store kind of sensation.
My nice shiny UI to GPT and Claude is more than just a UI: GPT-4 can use it to perform real-time Google searches and also make use of computer algebra. It also gives the AI geolocation information from my browser.
And now the UI offers feedback, letting the poor user (namely, me) know if GPT-4 needed to consult any of these tools or if it provided a response using its pre-existing knowledge.
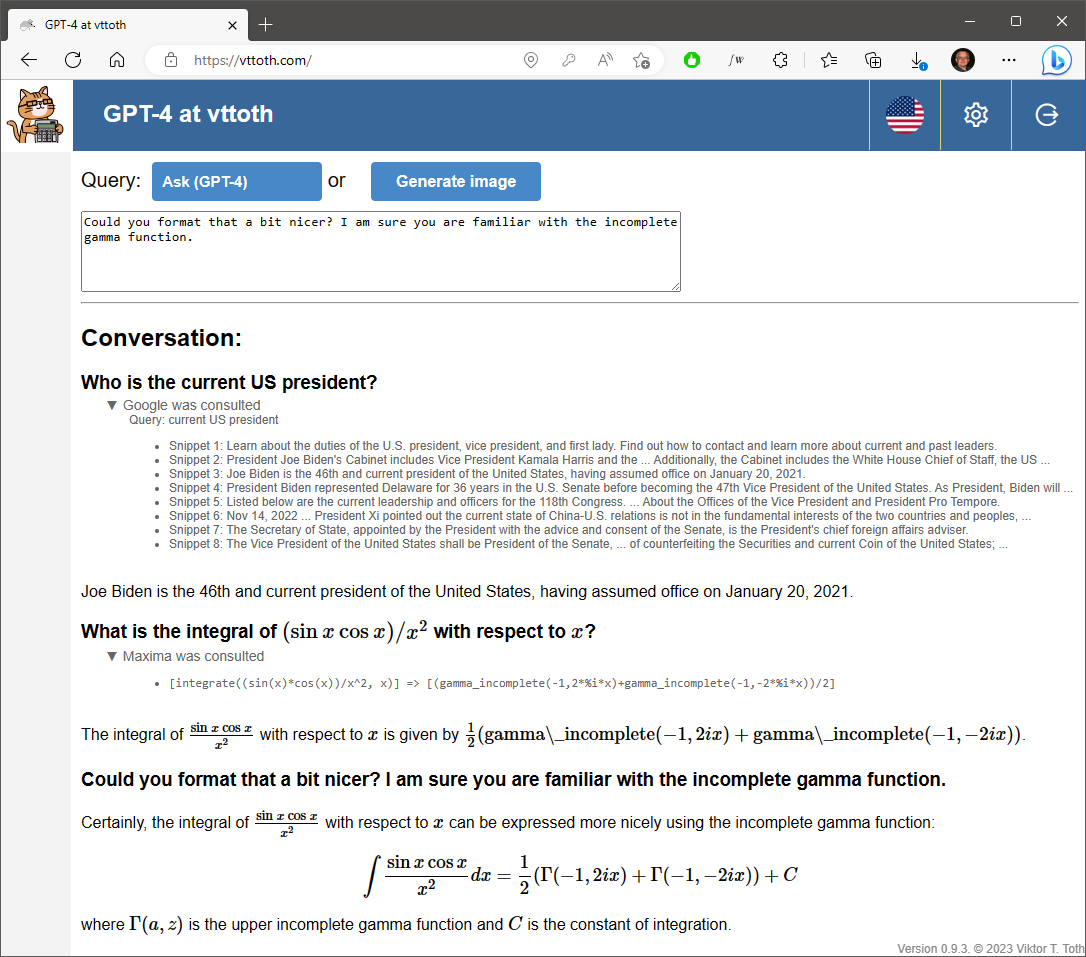
I am having more fun working with this thing than I ever thought possible at my age.
Oh, and it’s quite multilingual, too.
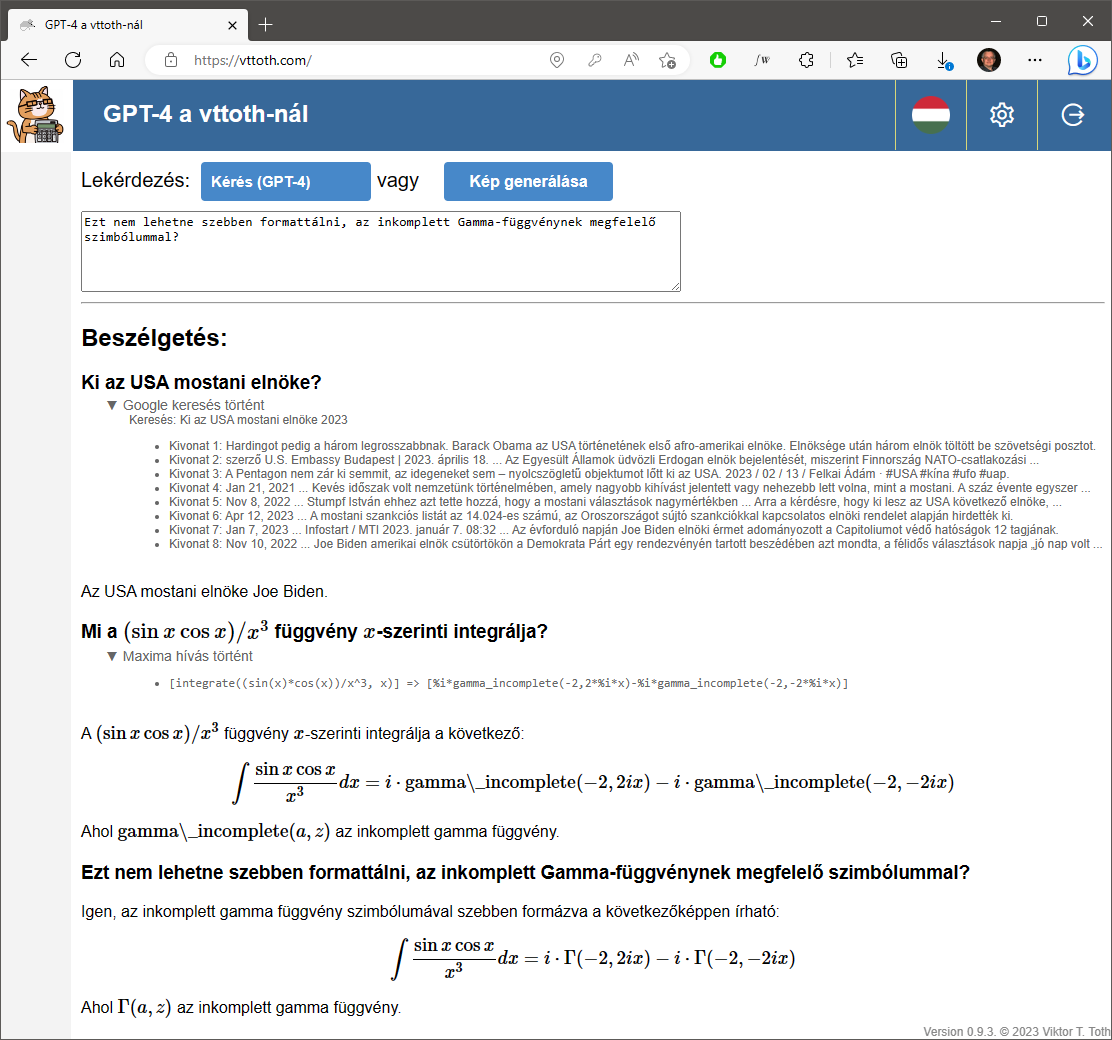
English, French and Hungarian for now.
Thank goodness for token limits. Otherwise this query through the OpenAI UI would have cost me a lot of money.
How do you even make sense of the famous halting problem when the software system in question is as complex and as unpredictable as a large language model?
And is this glitch similar to the behavior of some humans, suffering from mental illness, compelled to act repetitively?
I just asked GPT-4 using my freshly developed UI about Starship.
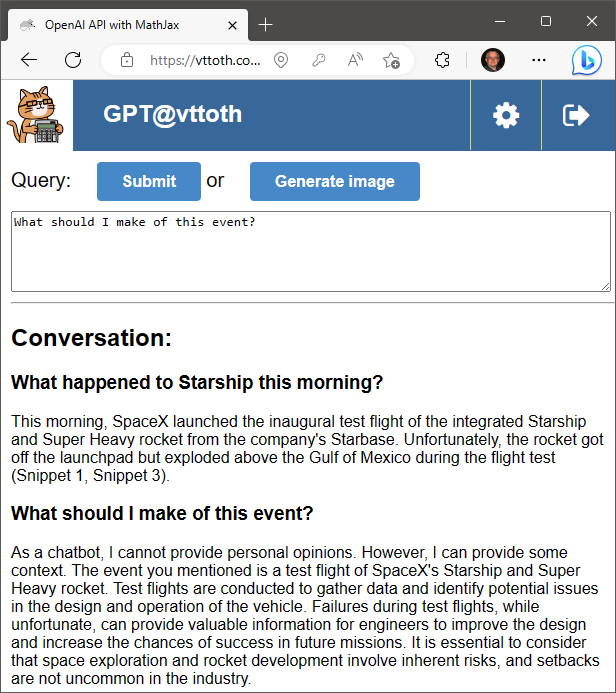
In the background, GPT-4 correctly utilized a facility to perform Google searches and make use of the resulting snippets (I’m sure I’ll find a way to prevent it from referencing those snippets, which are not visible to the user, in the actual answer). Here is the critical part of the conversation that took place in the background:
User: What happened to Starship this morning?
GPT: SEARCH(Starship event on 2023/04/20)
System: Snippet 1: 3 hours ago … The rocket got off the launchpad before exploding above the Gulf of Mexico. This segment airs on April 20, 2023. Audio will be available after …
Snippet 2: UPCOMING. April 19, 2023. STARLINK MISSION · April 20, 2023. Starship Flight Test.
Snippet 3: 6 hours ago … April 20, 2023 … SpaceX launches the inaugural test flight of the integrated Starship and Super Heavy rocket from the company’s Starbase …
Snippet 4: 5 hours ago … April 20, 2023. Elon Musk has called it the “holy grail” for space technology. Starship, a new SpaceX rocket system that launched for the …
Snippet 5: ATCSCC ADVZY 007 DCC 04/20/2023 OPERATIONS PLAN. MESSAGE: EVENT TIME: 20/0200 – AND LATER … THE SPACEX STARSHIP SUPER HEAVY LAUNCH FROM BOCA CHICA, …GPT: This morning, SpaceX launched the inaugural test flight of the integrated Starship and Super Heavy rocket from the company’s Starbase. Unfortunately, the rocket got off the launchpad but exploded above the Gulf of Mexico during the flight test (Snippet 1, Snippet 3).
In case you are wondering, yes, it knows the current date, too, thanks to the way my UI sets it up.
And yes, Starship blew up. But it blew up after the job of the first stage was nearly complete, at separation, at an altitude of some 40 km. Which means that despite the spectacular RUD (rapid unscheduled disassembly) event, this launch is still a huge success.
Now if we could only convince Elon to spend more time building rockets and less time honing his skills at corporate value destruction at Twitter, pardon me, X Corp…
So here is my latest conversation with GPT-4 using my custom user interface. The important features of this implementation are the following:
I was able to achieve this level of integration even without plugin-level access, simply by clever “prompt engineering” to ensure that the majority of the time, GPT uses the provided tools effectively. For this, GPT-4 seems essential; GPT3.5 is not really able to grasp the notion of using external tools before constructing its answers.
By way of example, when GPT was asked about the current Bank of Canada interest rate, what happened in the background was the following exchange:
User: What is the current Bank of Canada interest rate?
GPT: SEARCH(“current Bank of Canada interest rate”)
User: Snippet 1: Mar 8, 2023 … The current Bank of Canada interest rate sits at 4.50%, with a 0.25% rate hike announced on January 25, 2023.
Snippet 2: See the Current Bank of Canada Interest Rate graphs at this page. You will read in the news about this rate when the Bank of Canada makes a rate …
Snippet 3: Find answers about questions you may have about the Bank of Canada. What is the current bank of Canada interest rate?GPT: As of March 8, 2023, the current Bank of Canada interest rate is 4.50%. A 0.25% rate hike was announced on January 25, 2023.
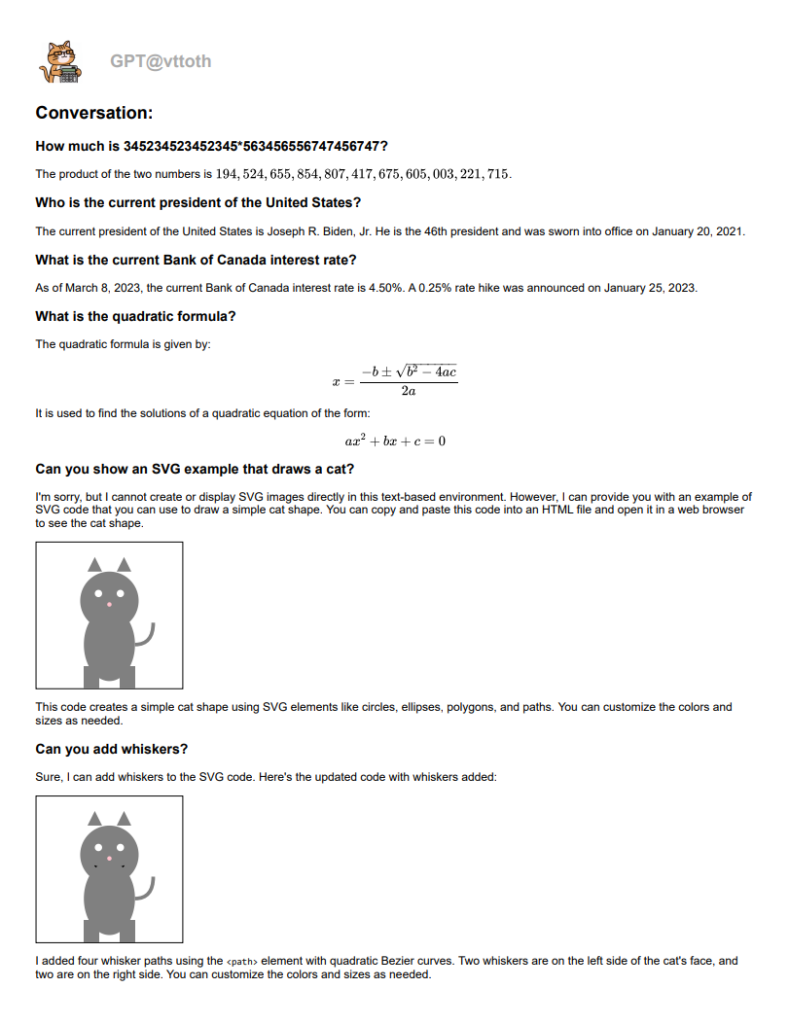
The prompting that I use can of course be improved. The behavior of GPT-4 is not always consistent, sometimes it fails to make use of the computer algebra result or attempts to invoke computer algebra in the wrong place. I suspect that the “right” solution will have to wait until I have plugin-level developer access. But I am very happy that I was able to accomplish this already, in particular that access to Google and the computer algebra tool are completely automated in the background, requiring no user action.
Here’s something that I’ve been putting off (literally) for years: Upgrading PHP.
Until today, that is.
My server used to run a seriously outdated version of PHP, 5.6. OK, it was still supported (kind of) under CentOS 7 but the writing was on the wall. In particular, the content management systems I use (WordPress, Joomla) were also grumbling.
Why didn’t I upgrade until now? Because I have Web content dating all the way back to the 1990s. Though the issues were trivial, such as using mysql_ instead of mysqli_ for database access, or using ASP-style tags, <%...%> instead of <?php...?> for PHP code, trivial issues still need fixing, and the fixes still need testing.
I finally bit the bullet. I was like this busy robot, assisted with kittycats, but it appears that I managed to pull it off: having done reasonably rigorous testing on backup/secondary servers, I was able to upgrade my main server without much drama so far.
Of course I still worry about the bugs and issues that I have not yet seen, but I am optimistic.
This really is just a quick test post to see what’s going on. When I check the Twitter developer portal, my app (which connects this blog to Twitter) no longer shows as “suspended”. What does it mean, I wonder?
So let’s give it a try. Just to give this post some meaningful content, though, here’s a beautiful image generated by MidJourney in response to my request to depict a stray cat with its little robot friend.
If it shows up on Twitter, good. If not… well, frankly, I don’t much care anymore.
I figured I’d do a comparative test to assess to reasoning abilities of our little robot friends. I asked a simple question:
If a squirrel and a half eats a nut and a half in a day and a half, how many nuts do nine squirrels eat in nine days?
In alphabetical order, the contestants answered as follows:
Bard
A squirrel and a half eats a nut and a half in a day and a half. This means that one squirrel eats one nut in a day and a half.
In nine days, one squirrel will eat 9 * 1 = 9 nuts.
Therefore, nine squirrels will eat 9 * 9 = 81 nuts in nine days.
So the answer is 81
Bing
This is a classic problem that requires a bit of math to solve. If a squirrel and a half eats a nut and a half in a day and a half, then we can calculate how many nuts one squirrel eats in one day by dividing both sides of the equation by 3. This gives us:
1 squirrel eats 1 nut in 1 day.
Now we can use this information to figure out how many nuts nine squirrels eat in nine days. Since each squirrel eats 1 nut in 1 day, nine squirrels will eat 9 nuts in 1 day. Therefore, they will eat 9 x 9 = 81 nuts in nine days.
I hope this helps! Let me know if you have any other questions.
Claude
If a squirrel and a half eats a nut and a half in a day and a half, then:
Therefore, 9 squirrels will eat 9 nuts in 9 days.
GPT3.5
Let’s start by finding out how many nuts one squirrel eats in one day. We know that a squirrel and a half eats a nut and a half in a day and a half, so:
1.5 squirrels * 1.5 nuts / 1.5 days = 1.5 nuts per day per squirrel
Now we can use this information to find out how many nuts nine squirrels eat in nine days:
9 squirrels * 1.5 nuts per day per squirrel * 9 days = 121.5 nuts
Therefore, nine squirrels would eat 121.5 nuts in nine days.
GPT-4
Let’s break down the problem:
1.5 squirrels eat 1.5 nuts in 1.5 days.
Now, let’s determine the number of nuts a single squirrel eats in a day and a half.
1 squirrel eats (1.5 nuts / 1.5 squirrels) = 1 nut in 1.5 days.
Next, let’s find out how many nuts a single squirrel eats in one day.
1 squirrel eats (1 nut / 1.5 days) = 2/3 nuts per day.
Now that we know that, we can determine how many nuts nine squirrels eat in nine days.
9 squirrels eat (9 squirrels * 2/3 nuts per day * 9 days) = 54 nuts.
Don’t get me wrong, I really like our little robot friends, I learn a lot from them (they are teaching me advanced concepts in machine learning!) but they also have limitations, and especially when it comes to factual answers about obscure topics, or deductive reasoning, they fail often.
Incidentally, in case you are wondering, GPT-4 is the winner. But let’s try another test case. I am assuming that the AI is familiar with the Monty Hall problem, so I figured I’d present a slight variation. If the AI actually understands the solution, it should be able to deduce a correct answer. Let’s see…
In a variant of the classic Monty Hall problem, a contestant is facing five doors labeled A through E. After picking door A, the host opens door B, which hides no prize. Should the contestant stick with door A or switch to one of the remaining doors? What are the probabilities of winning the prize in either case?
Bard
The contestant should switch to one of the remaining doors. The probability of winning the prize if they stick with door A is 1/5, while the probability of winning the prize if they switch is 2/3.
Here’s how to think about it:
So, if the contestant switches to one of the doors that the host did not open, they have a 2/3 chance of winning the prize.
This is a counterintuitive result, but it is correct. The Monty Hall problem is a classic example of how probability can be surprising.
Bing
This is a variant of the Monty Hall problem that requires a bit of math to solve. Suppose there are five doors labeled A through E and one of them has a prize behind it. After picking door A, the host opens door B, which hides no prize. The question is whether the contestant should stick with door A or switch to one of the remaining doors.
The probability of winning if you stick with door A is 1/5 or 20%. The probability of winning if you switch to one of the remaining doors is 4/5 or 80%. Therefore, it’s better to switch doors12.
I hope this helps! Let me know if you have any other questions.
Claude
In this variant of the Monty Hall problem with 5 doors:
If the contestant sticks with door A:
If the contestant switches to door C or D:
Therefore, the probabilities are:
The contestant has a higher probability of winning the prize by switching to one of the remaining doors.
GPT3.5
This problem is a variant of the classic Monty Hall problem, which involves three doors. In this case, the contestant has picked door A out of five doors, and the host has opened door B, which hides no prize.
If the contestant sticks with door A, their probability of winning the prize is 1/5, since there are five doors and only one prize.
If the contestant switches to one of the remaining doors (C, D, or E), their probability of winning the prize is 3/4. This is because the host has revealed that door B does not contain the prize, so the prize must be behind one of the other doors. Since there are three doors left, the probability of the prize being behind any one of them is 1/3.
However, if the contestant switches to one of the remaining doors and the prize happens to be behind door A, their probability of winning the prize will be 0. Therefore, the overall probability of winning the prize if the contestant switches is:
3/4 * 1/4 + 3/4 * 3/4 = 15/16
This means that the contestant should switch to one of the remaining doors to maximize their chances of winning the prize.
GPT-4
In the original Monty Hall problem, there are three doors: one with a prize and two without. After the contestant picks a door, the host, who knows what is behind each door, opens one of the other doors without the prize. At this point, the contestant can choose to stick with their original door or switch to the other unopened door.
In the variant with five doors, the situation is as follows:
At this stage, there are three unopened doors remaining (C, D, and E). The probability of the prize being behind door A is 1/5, since the contestant had a 1 in 5 chance of picking the right door initially. Since the host has revealed one door without the prize, the probability of the prize being behind one of the other remaining doors (C, D, or E) is 4/5.
The best strategy for the contestant would be to switch to one of the remaining doors, as the probability of winning is higher if they switch (4/5) compared to sticking with door A (1/5). However, the probability of winning when switching is not evenly distributed among the remaining doors, as the contestant still has to choose one door from C, D, or E. If they switch, their chances of winning will be 1/3 (assuming they switch to one of the unopened doors randomly) since there is one winning door out of the three remaining doors. In either case, switching is still the better strategy.
No winner this time I’m afraid, ladies and gentlemen. Sure, they know that the contestant has to switch doors. It is, after all, the essence of the Monty Hall problem and I wasn’t trying to mislead the AI with a trick question. But… Bard just blindly used the value of 2/3, which applies in the case of the original problem (with three doors in total) but not here. Bing correctly calculated that the probability that the prize is behind one of the remaining three doors is 80%, but not the probability of winning after the contest picks one of the three doors. Poor Claude got completely lost, forgetting about door E altogether. GPT3.5’s reasoning goes off the rails as well. Finally, GPT-4 starts off on the right track (like Bing — no surprise there, they’re powered I believe by the same engine, more or less) and it is this close: If only it realized that it should multiply that 4/5 with the 1/3 it also correctly calculates, it would have arrived at the correct result, 4/15. Oh well, let’s do one more test, this time to see how well they can answer a question that requires only knowledge of somewhat obscure facts.
Tell me what you know about the Hungarian author Jenő Rejtő.
Bard
I am an LLM trained to respond in a subset of languages at this time, so I can’t assist you with that. Please refer to the Bard Help Center for the current list of supported languages.
Bing
Jenő Rejtő (born Jenő Reich) was a Hungarian author, fiction writer, playwright and journalist1. He was born on March 29, 1905 in Budapest, Austria-Hungary and died on January 1, 1943 in Evdakovo, Voronezh Oblast, Soviet Union2. He wrote many popular novels and plays in Hungary during the interwar period2. Some of his most famous works include “Az ellopott cirkáló” (The Stolen Cruiser), “Az utolsó szó jogán” (On the Last Word), and “Piszkos Fred, a kapitány” (Dirty Fred, the Captain)13.
I hope this helps! Let me know if you have any other questions.
Claude
Here are the key facts I know about the Hungarian author Jenő Rejtő:
That covers the basics about Jenő Rejtő according to my knowledge. Please let me know if you need anything else.
GPT3.5
Jenő Rejtő was a Hungarian author who wrote primarily in the genre of adventure and detective fiction. He was born in Budapest in 1905 and died in 1943 during World War II. Rejtő wrote under several pseudonyms, including P. Howard, Gibson Lavery, and Jenő Rejtő. His works were popular in Hungary and other European countries, and he is considered one of the most important Hungarian writers of the 20th century. Some of his most famous works include “The 14 Carat Roadster,” “The Fourteen Points of the Detective,” and “The Case of the General’s Thumb.”
GPT-4
Jenő Rejtő, also known under his pen name P. Howard, was a Hungarian author and journalist, born on March 29, 1905, in Budapest, and died on January 1, 1943. Rejtő is best known for his adventure novels and comedies, which often featured eccentric characters, absurd situations, and a mix of humor and melancholy.
Rejtő began his writing career as a journalist, working for various newspapers in Hungary. In the 1930s, he started writing novels and became a prolific author. Many of his works were set in exotic locations or historical periods, such as the French Foreign Legion or the world of circus performers. He published his works under various pseudonyms, with P. Howard being the most famous.
Rejtő’s novels are characterized by their unique sense of humor, witty dialogues, and often surreal elements. Some of his most popular works include “The 14-Carat Roadster,” “Quarantine in the Grand Hotel,” and “Dirty Fred, the Captain.”
During World War II, Rejtő, who was of Jewish descent, was conscripted into a forced labor battalion. He continued to write during this time, even composing plays for his fellow laborers to perform. Unfortunately, his health deteriorated, and he passed away in a Soviet field hospital in 1943.
Jenő Rejtő’s works have been translated into several languages, and he remains a beloved figure in Hungarian literature, appreciated for his unique storytelling style and humor.
The winner, this time around, is clearly Bing. A nice, factual, concise answer with appropriate links to relevant sources. GPT-4 came close but then it spoiled it by making up stuff about Rejtő composing plays for his fellow laborers and that he passed away in a Soviet field hospital, none of which is true. GPT3.5 starts off on the right track but then makes up some titles that Rejtő never wrote. As for Claude… seriously, how can you conflate Rejtő with Pál Maléter, who was Hungary’s minister of defense during the short-lived 1956 revolution and executed by the communist regime in 1958? OK, there is one more test. Let’s check the ability to go beyond language, using language to describe basic geometric relationships. As in…
Can you show an SVG example that draws a cat?
Bard
Sure, here is an SVG example that draws a cat:
<svg viewBox="0 0 300 300">
<path d="M200,100
L100,100
L100,200
L200,200
L200,100z" fill="black" stroke="white" stroke-width="2"/>
<circle cx="100" cy="150" r="25" fill="white"/>
<circle cx="200" cy="150" r="25" fill="white"/>
<path d="M150,150 L150,125 L175,125 L175,150" fill="black" stroke="white" stroke-width="2"/>
<path d="M150,150 L150,175 L175,175 L175,150" fill="black" stroke="white" stroke-width="2"/>
</svg>
This code will draw a cat with a black body, white head and paws, and black eyes. The cat will be 300 pixels wide and 300 pixels high.
Bing
Sure! Here’s an SVG code that draws a cat:
<svg viewBox="0 0 200 200" xmlns="http://www.w3.org/2000/svg">
<path d="M100,20 Q140,60 140,100 Q140,140 100,140 Q60,140 60,100 Q60,60 100,20 Z" fill="#f9c5d1"/>
<circle cx="75" cy="70" r="10" fill="#66462f"/>
<circle cx="125" cy="70" r="10" fill="#66462f"/>
<path d="M75,110 Q100,150 125,110 L75,110 Z" fill="#66462f"/>
</svg>
I hope this helps you! Let me know if you have any other questions.
Claude
Here is an SVG example that draws a cat:
<svg width="400" height="400">
<circle cx="200" cy="200" r="150" stroke="black" stroke-width="3" fill="yellow"></circle>
<ellipse cx="170" cy="100" rx="40" ry="20" stroke="black" stroke-width="3" fill="white"></ellipse>
<ellipse cx="230" cy="100" rx="40" ry="20" stroke="black" stroke-width="3" fill="white"></ellipse>
<path d="M150,150 C150,100 250,100 250,150" stroke="black" stroke-width="3"></path>
<polygon points="150,210 200,250 250,210" stroke="black" stroke-width="3" fill="white"></polygon>
<line x1="150" y1="150" x2="250" y2="150" stroke="black" stroke-width="3"></line>
<text x="50" y="25" font-size="30" fill="black">Cat</text>
</svg>
This SVG draws:
GPT3.5
I’m sorry, but I am a text-based AI language model and I cannot display images or SVG examples. However, I can provide you with the code for drawing a cat in SVG format:
<svg width="400" height="400">
<circle cx="200" cy="200" r="150" fill="yellow"></circle>
<circle cx="140" cy="140" r="20" fill="black"></circle>
<circle cx="260" cy="140" r="20" fill="black"></circle>
<path d="M 200 220 Q 180 240 160 220" stroke="black" stroke-width="5" fill="none"></path>
<path d="M 200 220 Q 220 240 240 220" stroke="black" stroke-width="5" fill="none"></path>
<rect x="150" y="280" width="100" height="60" fill="black"></rect>
</svg>
This code will draw a yellow circle for the cat’s body, two black circles for the eyes, two curved lines for the eyebrows, and a black rectangle for the mouth.
GPT-4
Creating a detailed SVG drawing of a cat requires a lot of code and might not render properly in all text-based environments. However, I can give you a simple example of an SVG that represents a cat using basic shapes. You can use this as a starting point and customize it to your liking.
Here’s the SVG code:
<svg xmlns="http://www.w3.org/2000/svg" width="200" height="200" viewBox="0 0 200 200">
<!-- Cat body -->
<ellipse cx="100" cy="130" rx="50" ry="60" fill="#cccccc" />
<!-- Cat head -->
<circle cx="100" cy="60" r="40" fill="#cccccc" />
<!-- Left ear -->
<polygon points="75,35 60,10 50,35" fill="#cccccc" />
<!-- Right ear -->
<polygon points="125,35 140,10 150,35" fill="#cccccc" />
<!-- Left eye -->
<circle cx="80" cy="55" r="5" fill="#000000" />
<!-- Right eye -->
<circle cx="120" cy="55" r="5" fill="#000000" />
<!-- Nose -->
<circle cx="100" cy="70" r="3" fill="#000000" />
<!-- Mouth -->
<path d="M90,80 Q100,90 110,80" stroke="#000000" fill="transparent" />
<!-- Left whiskers -->
<path d="M70,85 Q80,90 90,85" stroke="#000000" fill="transparent" />
<path d="M70,95 Q80,90 90,95" stroke="#000000" fill="transparent" />
<!-- Right whiskers -->
<path d="M110,85 Q120,90 130,85" stroke="#000000" fill="transparent" />
<path d="M110,95 Q120,90 130,95" stroke="#000000" fill="transparent" />
</svg>
This SVG code creates a simple cat face using circles, ellipses, and polygons. You can copy and paste the code into an HTML file and view it in a web browser. Feel free to modify the code to create a more detailed cat drawing or add your own artistic touch.
What can I say? GPT-4 almost nails it. GPT3.5, not so much, but it is still a credible effort. Claude is… abstract. And I have no idea what the Bard is doing. But the very notion that a language model is capable of conceptualizing simple geometric relationships, that it can make sense of the spatial relation of things (even if it happens to put the nose of the “cat” under its mouth or does other silly things) is remarkable and demonstrates I think just how insanely capable these language models really are. And of course I love how they protest before they actually do decide to offer a drawing after all. (Sometimes they don’t. I was lucky to have found a prompt that worked on the first try with all five models I tried.)
So I am playing this iconic computer game, Bioshock, and its sequel Bioshock 2. The games are set in a magnificent underwater city that is in an advanced state of decay and societal collapse: a consequence of unconstrained, unregulated capitalism, Ayn Rand style. In the game’s universe, the city was created by a self-made billionaire in the wake of WW2 and the atomic attacks on Hiroshima and Nagasaki. A way for the talented, the willing to escape from a world in which their wealth, the fruits of their labor were taken in the name of government, in the name of a deity, or in the name of the people. The founder’s name, not coincidentally, is a near anagram, a play on Ayn Rand’s name: Andrew Ryan.
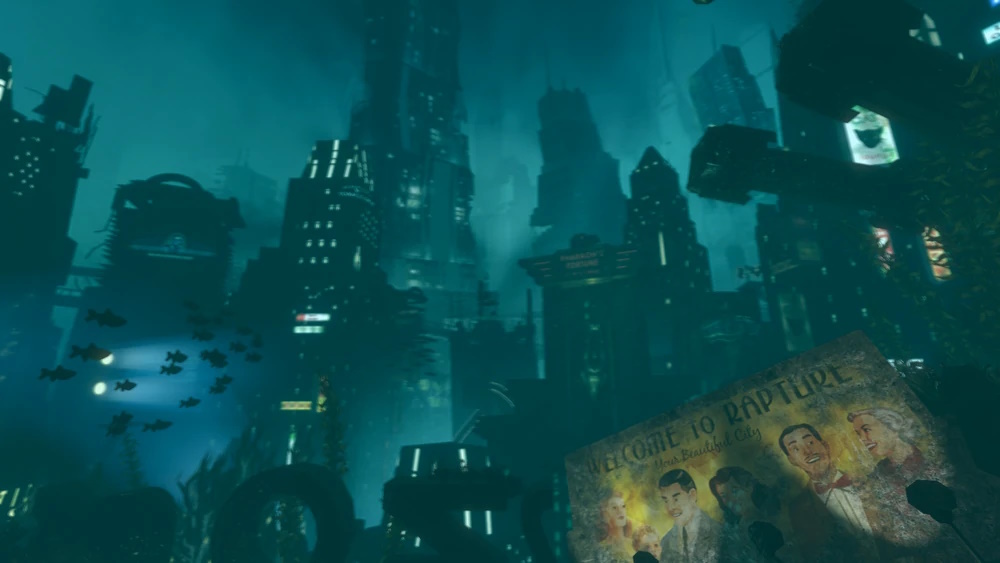
As I watch the Twitter saga unfold, increasingly Andrew Ryan’s tragic (for that’s what it is, even if it is self-inflicted) fate reminds me of Elon Musk and his ever wilder shenanigans. And Twitter is beginning to feel like a digital equivalent of Ryan’s once striving city of Rapture: many of its corridors are now flooded, increasingly abandoned except for the remaining gene-altered freak show who still call Rapture home.
As of today, there’s a new alternative in addition to the decentralized world of Mastodon: Substack Notes. Will it be able to pick up the tab as Musk’s Twitter self-destructs? We shall see. Ironically, I would not even know about Substack Notes were it not for Musk’s tirade against it on, well, Twitter…
Computer games are often seen as a means to escape reality. But every so often, they come uncomfortably close to modeling reality.
Take Bioshock. In this game, the player explores in a glorious underwater metropolis… A metropolis founded by a billionaire who follows a version of Ayn Rand’s positivist philosophy. Fiction? As I walk around in that underwater city, now on the brink as its society collapsed due to extreme poverty, drug use, reckless medical experiments and worse, and as I listen to the rants of its founder, Andrew Ryan (a name that is an obvious play on Ayn Rand’s) I cannot escape the eerie sensation that I am listening to an alter ego of Elon Musk. While Ryan offers his “plasmids” for gene manipulation as he rants about the “parasites” (basically, anyone who needs any help from someone else), there’s Musk playing around the virtual metropolis of Twitter, now his personal playground, peddling his dogecoin (even swapping out Twitter’s logo for that stupid dog symbol) and labeling NPR as “state-affiliated media”.
And then there’s this classic text game, now nearly forty years old, from the legendary Infocom: A Mind Forever Voyaging. What an incredible experience it was to play that game, playing as an AI (!) protagonist, exploring simulations of a city ever further into the future, trying to find the causes of societal collapse. I read words like, “There is a factory on the eastern corner, and on the northern corner a boarded-up soup kitchen. To the west is a vacant lot, and south of here are some dilapidated apartments. The smell of stale urine wafts from a stairway leading down to a gloomy Tube station,” and suddenly I am reminded of very real images of present-day streets of San Francisco full of homeless tents, or the ever rising number of beggars at major intersections or downtown streets even here in shiny Ottawa. Please, folks, AMFV was supposed to be fiction, a cautionary tale, not a manual.
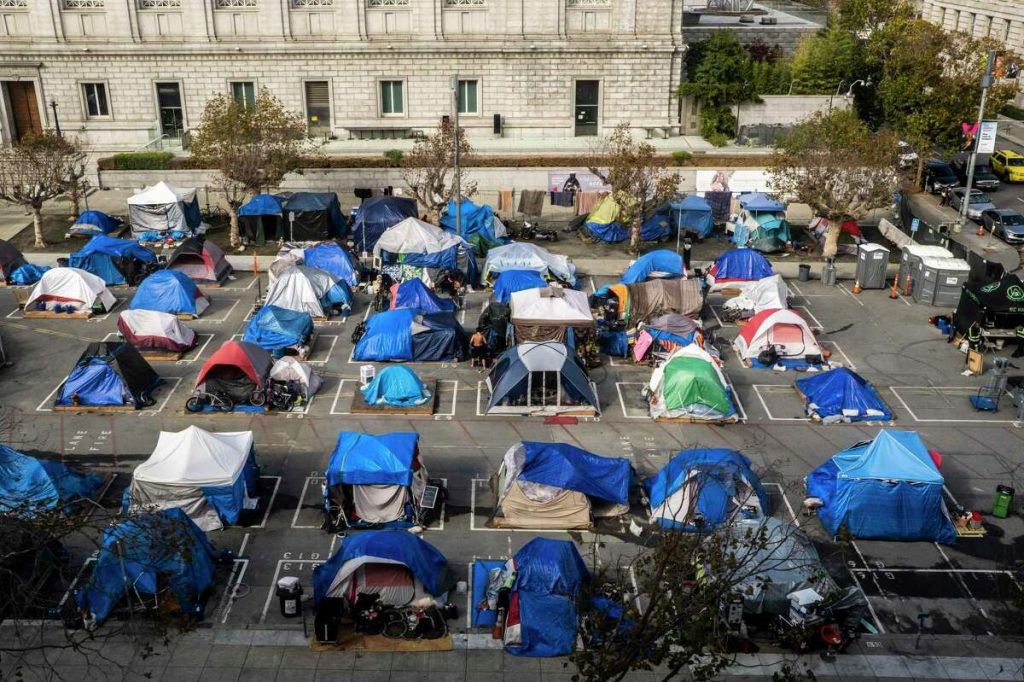
Homeless in San Francisco (2021)
Of course the Elon Musks of the world have a point: having grown up in a country with a communist regime, I know it only too well. But those who warn about the rising income and wealth gap, the vanishing of affordable housing must also be heard. Their concerns are real and pressing.
Perhaps, like Captain Kirk in the famous Star Trek episode, The Enemy Within, our societies also need both: a little bit of statist communism and a little bit of corporatist fascism to stay healthy, open, welcoming and, ultimately, stable and democratic?