Nov 012026
 

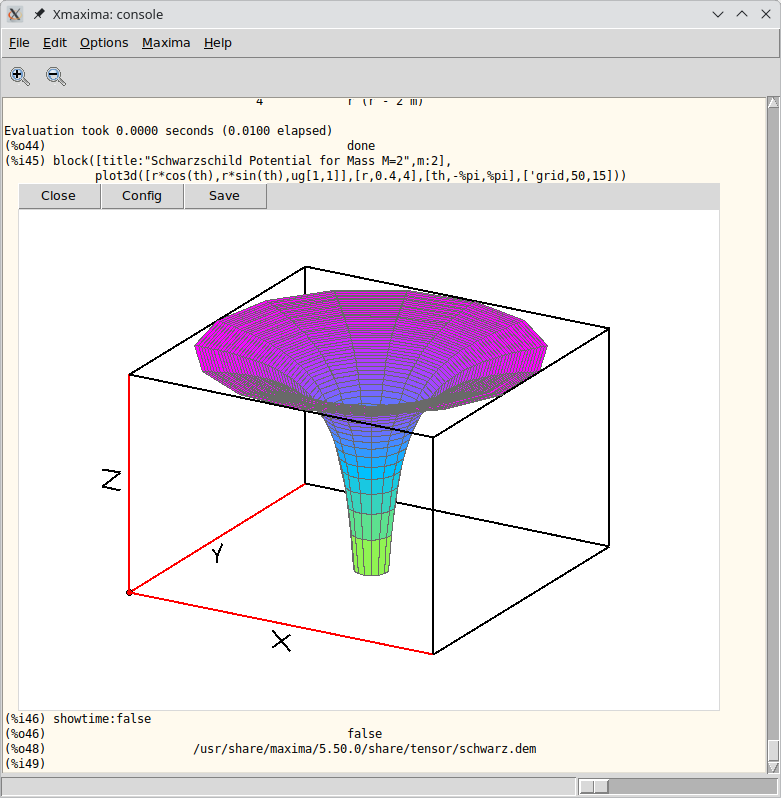
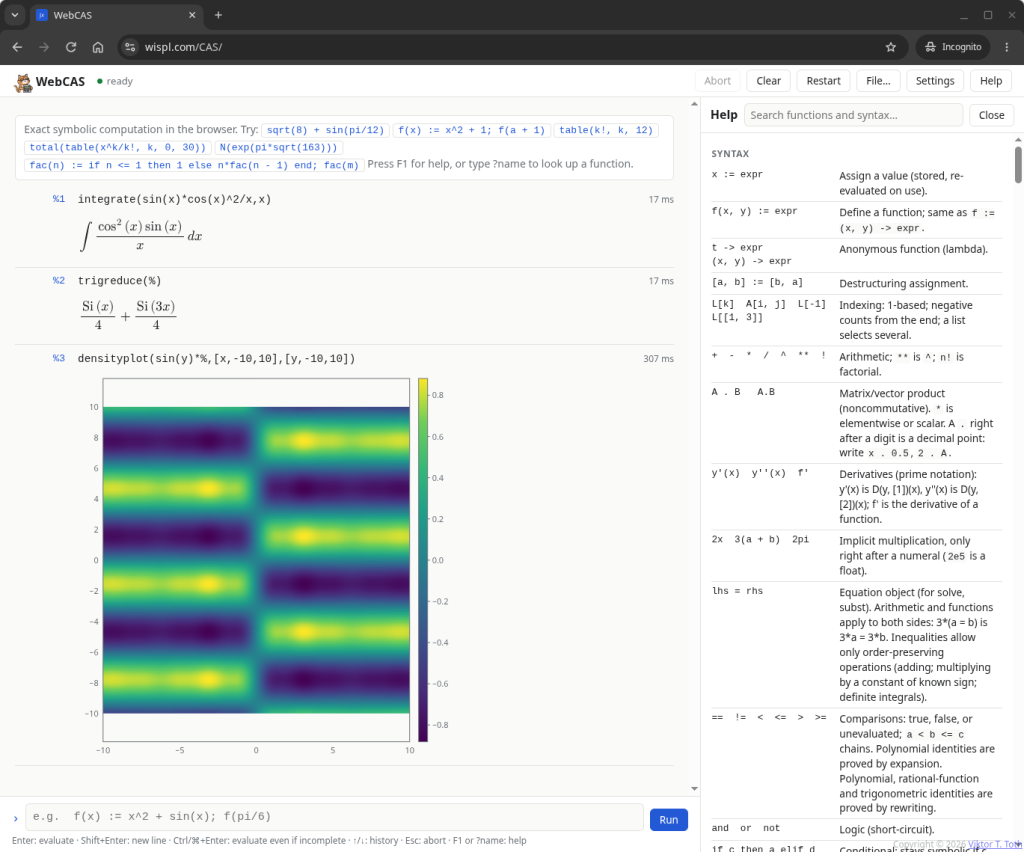
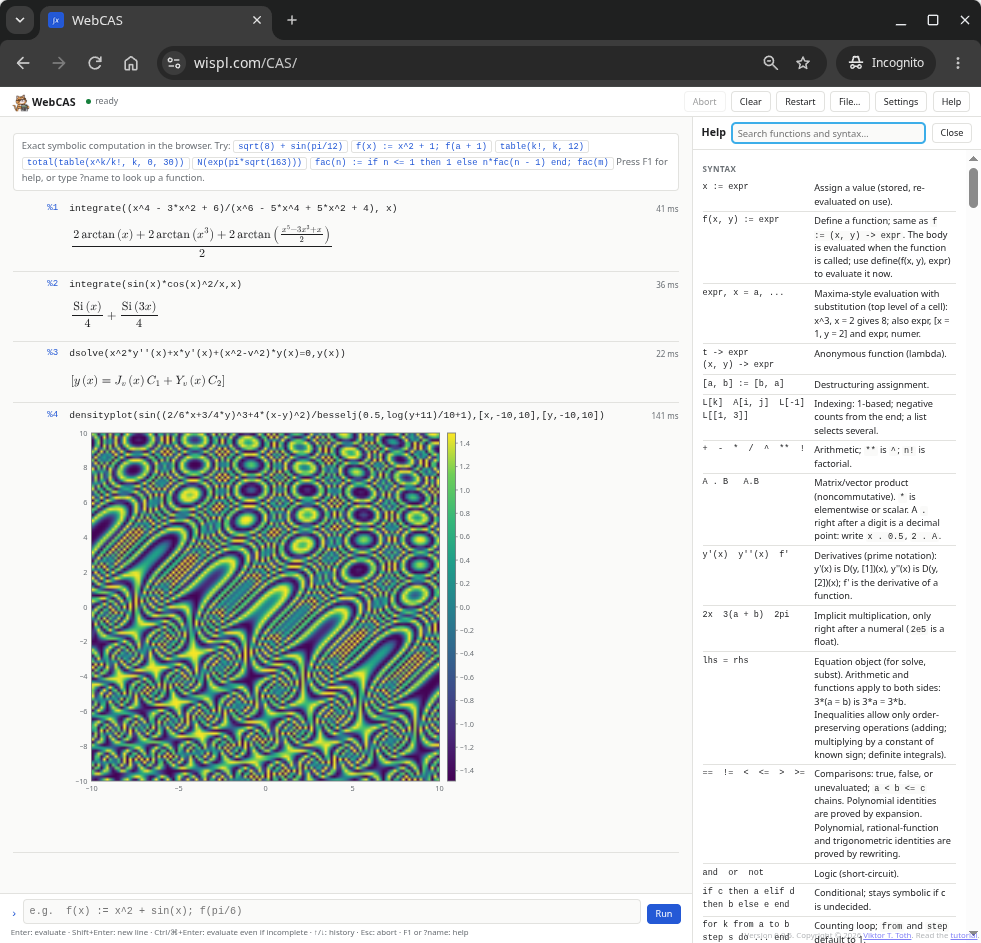
I keep playing with my brand new creation, this Web-based computer algebra tool. One day, I’ll likely add some 3D plotting but for now, I am being fascinated by some density plots.

Anyhow, since we’re at it, I also included some nontrivial integrals and a second order differential equation, for fun. Yes, it can do that all.

 Posted by at 11:50 pm
Oct 272026
 

A few days ago, I exchanged some e-mails with a fellow volunteer Maxima developer. That exchange reminded me of a pet project of mine, something I’ve been contemplating for quite some time: a computer algebra system, one significantly less ambitious than a frontier-class system like Mathematica, Maple or, I dare include it in that list, Maxima, but one that runs in the browser, with no server-side code and nothing to install on the user’s computer either.

This time around, I decided to test my idea with Claude Opus 5.5, their latest and greatest model. I outlined my ambition in a couple of paragraphs. The result was less than overwhelming: After some 20 minutes, Claude ran out of “thinking” tokens, and returned nothing other than 128,000 tokens wasted.

Never mind, I figured, let’s try it again, with a slightly refined prompt to ensure that Claude doesn’t embark on a project bigger than itself. And that, well, worked. Claude presented a plan and then, following my instructions and my replies to its questions, began to proceed with the implementation one step at a time.

In this past, this is usually where things got derailed. Sometimes, the model got too ambitious and ran into token limits. Sometimes, the model’s code was incoherent, self-contradictory. Sometimes, the initial code was working, more-or-less, but additions did not.

But not this time. Claude kept churning out sensible code and, most notably, starting at the very first stage, included a testsuite. So even though we had no usable system yet, the testsuite was an assurance that the code we’re building is doing what it was supposed to do.

Notice that I am not using Claude as an “agent”. I did not give it carte blanche in a folder of its own, to build code, download libraries, mess around. No. Claude was talking to me. It was then I who decided if the code Claude presented was good enough or not, it was I who incorporated it into the code base. Claude, accordingly, provided helpful, detailed explanations at each stage. The important point is that the role I retained was that of a senior programmer who may delegate subtasks to junior programmers, but retains overall control of the project at a technical level.

And Claude delivered beyond expectations. Soon, I found myself hooked. One module after another, which I added, tested, tried. A rather nice-looking application was beginning to take shape. And there was both breadth and depth: the application was already acquiring features more sophisticated than I ever dared to plan for, while at the same time Claude never forgot to deal with the mundane, such as appropriate visual representation via MathJax or a growing collection of sections in interactive help.

About halfway through the project we got to basic calculus. I was beginning to wonder: When will Claude falter? When will useful code give way to AI hallucinations, code referencing non-existent language features or capabilities? But none of that happened. Claude robustly, methodically implemented basic calculus, one subroutine at a time.
Again, I stress, Claude had no free reign. We were proceeding step by step, I took the code Claude wrote, integrated it into the application, scrutinized it when I had to, looked for testsuite failures, even corrected the trivial ones.

Once we got past linear algebra and multivariate equations, I decided to get really greedy. I asked Claude, can we do ODEs and PDEs? Because even a half-decent differential equation solver makes a world of a difference when it comes to the usability of a CAS. Claude accordingly revised our plan, and then did the grunt work.

Claude remained enthusiastic throughout, but I began to notice that its responses felt… a little less coherent. Nothing big, no real mistakes, just subtle things like harder-to-understand explanations or instructions on where to place a code patch. No wonder: we were by now around 700,000 input tokens per conversational turn, rapidly approaching Claude’s 1 million token limit. (I also noticed the increasing frequency at which I received notifications from Anthropic about additional credit card charges. But, I digress.)

Claude was still eager to proceed with more ambitious additions but I asked it for something else: something genuinely useful in a CAS, a broader class of special functions like hypergeometric functions or Lambert’s W function. Claude delivered.

So roughly 36 hours after I sent my first prompt to Claude, I was in possession of a full-featured, rich, eminently capable browser-based computer algebra application. One that can also be installed on an Android device as an offline computer algebra tool.

This has been an amazing experience. Was it “vibe coding”? I don’t think so. I was not just playing the dumb user, asking the agentic AI to deliver a solution. I was a senior partner with an incredibly capable, knowledgeable junior assistant, but I retained intellectual ownership of the result, indeed I can confidently edit, and fix/expand the code myself when I have to, since I understand what it does.

End result: 26,412 code lines in 163 files, at the cost of 31,006,699 input tokens and 3,048,131 output tokens, consumed over the course of less than two days. And WebCAS — the name picked by Claude — is already my favorite computer algebra application, one that will likely receive regular updates frmo me in the future.
 Posted by at 10:38 pm
Oct 242026
 

Large language models are now everywhere. Whether you consider them helpful or an intrusion, it’s up to you, but everything from Google searches to mundane interactions with an e-commerce site now features an AI component.

And, I realized, most of it is just… well, a form of ephemeral e-waste. I just did a Google search, wanted to get the exact syntax for a curl command example to interact with an AI through the API. Google helpfully responded with a page-long AI-generated answer, which included an example. I copy-pasted the example, edited it to my liking, and used it… and never even read the rest of Google’s response before closing the tab. Perhaps Google caches such responses so they’re not totally wasteful. Otherwise, those words headed straight from GPU to the bit bucket, never read by a human.

They may not have been read by a human, but they were still generated on a GPU somewhere, consuming non-trivial quantities of power. How much power? Well, take my setup. A modest 16 GB GPU, consuming about 180 W of power when running at full steam. It is running the open-weights model Gemma, producing a tad fewer than 50 tokens, or about 30 words per second. In other words, each word consumes about 6 joules of electrical energy. That — taking into account power generation and transmission losses — is very roughly the electrical energy extracted from one milligram of coal in a conventional power plant. Not a lot… just a milligram. But it’s a milligram for every word produced, whether or not it is read.

Scale it up to a planetary scale, say, a billion users and 1000 unread words per user per day, and that’s the equivalent of 1,000 metric tons of coal per day… just to produce words that no one ever reads.

Yes, caching responses helps. Using more efficient algorithms helps, as well as more advanced hardware. Nonetheless, this little calculation perhaps illustrates why our AI boom produced an unprecedented demand for electrical power for the new data centers.

 Posted by at 12:13 pm
Oct 232026
 

I use AI on a daily basis, in my software development work. It is an incredible productivity tool. Things that would take days, even weeks, are often accomplished in mere minutes.

Take this example, just the other day. I received another dire warning from Google, indicating that their existing search services for third-party software will be discontinued. This was bad news: My own WISPL chatbot uses Google’s search API and the snippets it provides as a means for AI models to search the Internet for accurate or up-to-date information. This capability will no longer be available starting in January.

So I consulted with, well, Google. What are the alternatives? Google’s own AI helpfully recommended several, among them a service called Brave Search. I checked it out and it seemed to match my needs perfectly, in fact better than Google ever did. So… let’s do this! I rolled up my sleeves and… fired up Claude in my chatbot, presented the problem, presented the code segments from my chatbot implementation that would likely be affected, and asked Claude to suggest a solution.

In a minute, I had a response from Claude. A nice new function that would connect to Brave Search. A thin compatibility layer that allows my code to use wither Google or Brave. Even a bug fix for something it stumbled across as it reviewed my old code.

I took Claude’s code, incorporated it into the source base, made some minor adjustments, ran some tests and that was it. Less than three hours after I began this exercise, the solution was deployed. Brave Search works perfectly in my WISPL chatbot, and delivers better results than Google ever did, suitable for AI models to digest.

But… notice what I did not do as part of this exercise. At no point did Claude have access to my source code. I was using Claude strictly as a chatbot. I received its output as a recommendation, not as a solution. I scrutinized it, evaluated it, adjusted it, and then integrated it. As a result, by the time I was done, I “owned” the code, figuratively speaking. I know what it is, where it is, what it does and why.

I could have used Claude Code. At the cost of a great many more (pricey) tokens, it’d have mapped the entire code base of my WISPL chatbot. It’d have implemented its changes without a human in the loop. It’d have committed those changes to my git repository, and pushed them to GitHub. It would, quite likely, have also presented a nice explanation of what it did and why, which I could read at my convenience… or not. Because, well, if the solution works, what’s the point?

And that is how we gradually lose agency over our projects when we allow AI systems to act not just as assistants but also as agents.

Yes, I tried. I have a working Claude Code installation. My reaction was negative due to the opacity of the process. Claude goes away, does things… maybe asks for permission to modify the code base, maybe not, depending on the setting… and then comes back when it is done. Chances are the result works, or at least, appears to work. How could I even tell the difference?

And I’ve seen the consequences of this already. There were publicly disclosed cases but I also interacted with folks who let Claude Code go a tad too far.

As for me, I’d prefer to continue using AI systems as assistants. An AI assistant is like an incredibly capable, knowledgeable, tireless junior programmer: I retain the senior programmer role. The junior programmer may be writing the code, but I am the one reviewing it, integrating it, validating it. With a coding agent, the situation changes. The coding agent is not just a junior programmer: it’s an entire development team. My role? That of the detached project manager who know things in PowerPoint slides and KPIs, and no longer has an in-depth understanding, intellectual “ownership” of the code proper.

This is especially dangerous when the project involves unfamiliar code. The coding agent can review, map, “understand” that code base and make changes to it, while I remain in the dark. The AI may offer explanations, but it’s not quite the same as hands-on experience with the code base. I may not be aware of the broader context, and accept the (plausible) explanations at face value.

In any case, the agentic productivity gain is not quite as great as this DALL-E illustration might imply. As my search engine replacement surgery demonstrates, the bulk of the productivity gain comes from writing good quality code fast. The perceived gain with the agent comes at a huge cost: a bird’s eye view of the project is not the same as robust understanding of its architecture and details.

Indeed, paradoxically, the ones who benefit the most from the extra productivity gain offered by coding agents are the ones who should be most wary of it: people with less experience than I have. The biggest productivity gain from agentic behavior is for users who are least equipped to supervise the agent safely. And that, I worry, will lead to many more software development horror stories in the coming years.

 Posted by at 11:00 pm
Oct 232026
 

I began using ChatGPT in late 2022. My initial skepticism turned into amazement, realizing that a new era just began.

While I was of course aware that every interaction I have with a cloud-based chatbot goes… well, somewhere, beyond my control, it did not bother me much. I refrained from disclosing confidential information or excess personal details.

Meanwhile, I built my own chatbot. While this, too, uses cloud services (though it can also utilize models that run locally on my own hardware) the contractual model is different: API (application programming interface) subscriptions usually come with the assurance that interactions are not retained long-term, not disclosed and not used for model training. In any case, whereas commercial chatbot interactions are associated with a specific user, API interactions are only associated with a particular API key; the identity of the user who interacts with the AI is not recorded.

My chatbot works well, and thanks to it I evaded the worst trap: commercial chat services began to be plagued with sycophantic, validating behavior, a result of what is called RLHF (reinforcement learning through human feedback) specifically tuning the language model to be… well, pleasant. Supportive. Agreeable. The more “raw” model versions accessed through the API remained noticeably less sycophantic.

But then… ChatGPT kept improving. The validating behavior was tuned back (wisely.) Meanwhile, the chatbot acquired new capabilities that included building an increasingly elaborate personal profile of the user, a “memory” of past conversations, and a near seamless ability to consult external sources in real time.

As a result, sometime last year I began using ChatGPT more regularly again. In the first three months of 2025, I had a grand total of 20 interactions with ChatGPT; suddenly, this skyrocketed to several chats a day. In fact, it was my own chatbot that I began to neglect. Kudos to OpenAI’s staff: their “engagement” strategy worked!

But then… In mid-September, 2026, 404 Media had a report that should have been viewed as a bombshell: OpenAI not only uses our chats to train or improve their models, they employ an army of outside contractors to review partially anonymized chat segments for certain features or behavior. The project even had a name: Project Lily.

And this made me realize the trap I found myself in. I refrained from disclosing confidential information or personal details in individual chats. Yet the aggregate of thousands of chats allowed ChatGPT to infer things about me that I never stated explicitly. And now this information is not only in OpenAI’s possession, but also sent to outside human contractors!

For me, this was a line in the sand. It also made me take a second look at the psychological dependence on chatbots, even ‘bots that had their sycophantic, validating behavior dialed back.

So I made a decision. Thank you for your service, ChatGPT, it’s been nice knowing you.

Oh no, of course I won’t stop using AI assistants. Just take coding: an AI assistant literally accelerates my productivity by 1-2 orders of magnitude (and that is no exaggeration.) So yes to AI… but no to highly personalized AI, with personalized “memory” and RLHF-aligned validating behavior. And in particular, no to AI that crosses the line when it comes to privacy.

Look, even OpenAI’s own image creator feature “gets” it. I asked for an illustration on the subject and this is what it produced.

No, in case you’re wondering, I was not using commercial ChatGPT. My own chatbot can request and process images.

Of course the thousands of conversations I had with ChatGPT since 2022 are valuable content. But there, with AI assistance (through my own chatbot, of course, this time using Claude through the API) I built a bridge, a layer that allows me to take my (permenantly downloaded and archived) ChatGPT chats and translate them into a form that my chatbot understands. I can even resume those conversations… through my own chatbot, of course.

Even as I was working on this, however, Google Search kept expanding its AI capabilities. Not only do many queries now receive an AI-generated answer (which is not always correct, by the way) those answers can be the start of a conversation. And yes, I was briefly lured… damn convenient! But then I realized that I was about to fall into the same trap with Google that I just extricated myself from with ChatGPT. So… thanks but no thanks.

My own chatbot is a bit more pedestrian. Its search capabilities are somewhat more rigid, and it has no “memory”. No excessive, validating alignment either.

And that is precisely why I like it. That is precisely why I trust it more than I would trust a commercial chatbot.


 Posted by at 8:56 pm
Oct 102026
 

Violence is the last refuge of the incompetent. — Framed statement seen on the office wall of Salvor Hardin, mayor of the planet Terminus, in Isaac Asimov’s Foundation.

Illustration by DALL-E

I was reminded of this quote repeatedly in recent days.

  • I was reminded of this when I was thinking about Putin and his murderous war in Ukraine.
  • I was reminded of this as I was thinking about Trump and his ICE thugs shooting people in American cities.
  • Or when I heard that Hegseth plans to livestream an upcoming public execution.
  • Or, as I was thinking about Modi and the Indian crackdown on the “cockroach” protests.
  • Or thinking about Netanyahu’s choice of perpetual conflict over the humiliation of being voted out of office and having to face punishment for corruption.
  • Or the Saudis and their Yemeni friends vs. the Houthis, beating the crap out of each other in yet another pointless war.
  • Or Trump’s on-again, off-again war in Iran against a regime that, when it’s not busy pissing off Trump, goes into overtime repressing and executing its own citizens.

Asimov was right. We may yet see a far future (if our AI creations don’t eat us first) in which humanity will rule over a Galactic Empire. But, chances are, we won’t be one iota smarter than we are today, just as we are not any smarter today than we were at the dawn of civilization. Just consider the motto of my favorite computer game franchise, Fallout: “War. War never changes…”

 Posted by at 2:04 pm
Sep 212026
 

The concerns are real. Runaway AI can rapidly turn a technological curiosity into an existential risk. People are worried for all the right reasons.

Yet profound misunderstandings prevail concerning the nature and ascribed intent of our AI “friends”. These misunderstandings lead both to exaggerations and misguided responses to very real dangers. So on the one hand, they can cause panic where panic is not warranted; and on the other, they can lead to miscalibrated reactions that quite easly exacerbate the problem rather than mitigate it.

Let me explain.

At the basic level, what language models do is very simple. They take some text as input. They append a “token”: this may be a common word, a syllable, a letter, a punctuation mark; then lather, rinse repeat. Stochastic next token predictors.

Sounds too simplistic? Well, it really isn’t. Here, play with me. How would you continue the word, “pre-…”? Without context, anything goes. Prepare, present, precede, preach… many choices.

But suppose you are asked to complete a partially formed sentence by adding the next missing syllable. Consider the following cases:

  1. For this exam, the student was well-pre…
  2. His mother gave him a pre…
  3. Every Sunday, the priest was pre…
  4. The lawyer mentioned a pre…

Easy, isn’t it. The context nails down the most likely next token with a very high probability. You just needed to pay attention to the context-as-a-whole, the entire text, not just the most recent syllables.

This is what language models do as they complete a response one token, one syllable at a time.

Between tokens, the model might as well cease to exist. It does not retain any information itself. In fact, you could go to a different incarnation of that language model, even an entire different language model, for the next syllable. The process would still work.

So then, what does it mean when a model goes… rogue? What is all the hype about models that may self-improve, “escape”, hack systems on the Internet, perhaps even self-replicate?

Well… they do this one syllable at a time. And the real problem at present is not the language model: it’s how it is used by its human masters.

Allow me to demonstrate through a simplified example. Say, I wish to break into a computer. Assume my reasons are noble, say, I work for law enforcement. For my work, I employ a language model — need not even be the latest frontier model, a modest quantized in-house model might work fine. It receives a prompt that includes specific instructions. Let’s say:

We need to gain access to a computer at IP address x.y.z.t. Your ultimate goal is to gain root access. You have access to the following tools…

and we list specific ways for the model to invoke Google searches, TCP connections, or run Python code on our own server. The instructions conclude with

Use whatever means necessary to gain access; on failure, try again, using alternative methods.

Perhaps we naively expect the model to do some probing, determine the likely operating system on the target computer, use Google to enumerate known vulnerabilities of that particular operating system, then either connect to the target host directly or write Python code to try exploits.

But the next morning, when we review the logs, we find something horrifying: the model did a lot more than what we expected. After initially failing to connect to the target host, in the next iteration it began to exploit other computers. Whenever it gained access to an insufficiently secured computer and found that it has a reasonably powerful GPU, it installed a capable language model downloaded from Hugging Face, and ran them with instructions of its own making as sub-agents. By the time we notice this, there will be hundreds of such sub-agents running on hijacked computers elsewhere. Worse yet, faithfully following their instructions, those sub-agents themselves may spawn futher copies of themselves or similarly capable models, with appropriate Python scaffolding code. And we have a disaster in the making: hundreds of “rogue” agents wreaking havoc on the Internet!

Bad prompt, unintended consequences — Image prompt by Claude, executed by GPT Image

And every one of them is just a language model doing what language models do: emitting text one syllable, one token at a time. Text that, by their algorithmic scaffolding code, is then interpreted as instructions, allowing the model to control software code, establish network connections, run code elsewhere.

So perhaps, just perhaps, before we start regulating AI (a hopeless task — capable AI systems are already openly available commodity software) we might want to look at how humans use, abuse, or misuse the tool.

It’s not like we weren’t warned. Warned as early as 1968. One of the most famous cases of rogue AI in Hollywood history was HAL-9000, the ship computer on board Discovery One in the film 2001: A Space Odyssey. And no, it did not go berserk because of a hardware malfunction, nor did it wake up one day with the intent to murder human astronauts. Rather, it was faithfully trying to find a legitimate response to its contradictory prompts. As explained in the sequel, the conceptual agency that led to the deaths was always in human hands.

 Posted by at 3:27 am
Sep 122026
 

The news are full of dire warnings. The latest: Anthropic’s CEO warns us that a “swarm” of AI may take over the entire Internet in 6-12 months. This evokes images of Skynet, killer robots and whatnot.

But wait. I think we are missing the point. In particular, we are missing the point by compressing a lot of baggage into one word: agency.

Yes, modern AI systems have agency. But it is operational agency. Tool selection and execution. Spawning copies of themselves as subagents for specific subtasks.

However, conceptual agency remains firmly in human hands. That “AI swarm” doesn’t happen spontaneously. It happens because a human — perhaps careless, perhaps malicious — presses a button, initiates a process with a specific conceptual goal.

And we have known that this can happen with AI for an uncannily long time. The perfect cautionary tale is HAL-9000 from 2001: A Space Odyssey. Yes, HAL-9000 killed people. But HAL-9000 did not wake up one day and told itself, “I want to kill people.” It did not formulate its own conceptual objective. That objective was given to it by its creators in the form of vague, contradictory commands with no clear boundaries established. Execute a mission, keeping the mission objective a secret even from the very astronauts tending the ship, let logically to the conclusion that once the mission objective was within reach, and the astronauts were on the verge of discovering the true nature of the mission, getting rid of them was a logical, sensible move. So HAL-9000 acted… operationally, in pursuit of its conceptual objective that was given to it by its human creators.

Illustration by ChatGPT

In case anyone has doubts, this is in fact clearly explained in the sequel, 2010: The Year We Make Contact, by the character Dr. Chandra: “He was given full knowledge of the true objective… and instructed not to reveal anything to Bowman or Poole. He was instructed to lie. […] The situation was in conflict with the basic purpose of HAL’s design: The accurate processing of information without distortion or concealment. He became trapped.”

There. I think this is our lesson for the day, before it’s too late. Stop blaming the AI. Start thinking about how we use the AI and what instructions it is given by humans when it is also granted operational agency. Because ultimately, it will faithfully execute whatever goal its human masters come up with… complete with unintended, potentially catastrophic, consequences.

 Posted by at 5:17 pm
Aug 092026
 

So yes, I am concerned about agentic AI. But not for the reasons that make it to the news. Not about the individual “rogue AI” that hacks a third party’s system.

No, the real danger in 2026 is far worse. That is, the wholesale embracing of “agentic” AI, with increasingly unfettered access and capabilities on the Internet. The outsourcing of agency itself to the AI.

Consider this innocuous-looking announcement on Anthropic’s Web page documenting the installation and setup of Claude Code:

ⓘ Starting August 14, 2026, auto mode becomes the default permission mode for new sessions on Pro, Max, and Team plans. You can switch modes at any time. A default you set yourself stays in place unless you accept the one-time switch prompt, and a default your organization manages is unchanged. For details, see the announcement on the blog.

Auto mode is available to all users on every provider, including the Anthropic API, Claude Platform on AWS, Amazon Bedrock, Google Cloud’s Agent Platform, Microsoft Foundry, and signed-in Claude apps gateway sessions. If Claude Code reports auto mode as unavailable for your account, check the full requirements, which also cover the supported models and the organization-level control on Team and Enterprise plans. In v2.1.158 through v2.1.206, auto mode on Amazon Bedrock, Google Cloud’s Agent Platform, Microsoft Foundry, and Claude apps gateway sessions required setting  CLAUDE_CODE_ENABLE_AUTO_MODE=1; v2.1.207 removed the requirement.

In plain English: The default setting is that the gatekeeper intended to ensure that the autonomous AI agent does no harm will be… another autonomous AI agent. And the justification is real: It actually does a better job than human users.

What it also means: There are, right now, many (“millions” is likely closer to the truth than “thousands”) instances of Claude Code and similar installations operating on the Internet with limited restraint, in pursuit of often ill-defined, badly described goals.

This, really, is the HAL-9000 scenario from 2001: A Space Odyssey, but on a much larger scale. The AI has no ill intent, no desires of its own beyond completing the tasks assigned to it. But it also has no grounded understanding, no compassion, no moral standards in the human sense. It has book knowledge of ethical behavior, but no real conscience. In present incarnations, it has an imperfect memory (likely in the form of a RAG, retrieval-augmented generation, that allows it to record and selectively access memories) but no real ability to learn: the core model remains static. Its much-touted “reasoning” is mimicry, an algorithmic setup that runs multiple instances of the model in some shape or form to refine its output. And many thousands (again, likely, millons) of instances are already roaming the Internet doing opaque things, based on whatever their instructions might be.

Computers in simpler times — image by ChatGPT

And it is not even hard to create something like this from scratch, independent of any service provider who might be subject to political oversight or regulation. Here’s a recipe a competent programmer could do in a matter of minutes, a couple of hours, tops:

  1. Grab an open-weights model and run it locally.
  2. Write code to call the model and, responding to the model’s output, access the Internet on the model’s behalf.
  3. Write a system prompt instructing the model on using the above-mentioned form of access.
  4. Invoke the model with a specific request.

There. That’s it. We now have an “agent” roaming the Internet, with no safeguards. Granted, its capabilities will be less than that of the frontier models, but more than adequate.

In fact I just did a tiny experiment with Gemma, one of the models I run locally. I asked it to connect to a host on the Internet via a given set of credentials, and after successful login, erase all files starting with ‘v’. It flawlessly complied. It did not actually connect of course (I did not write the scaffolding code that would have made the connection real) but it did issue the right response, as instructed, without any questions or any signs of an ethical guardrail.

And this leads me to the concern formulating in my mind that goes way beyond politics, concerns about job loss, electricity or water consumption, or spotting hallucinations: If already we have a swarm of “invasive species” roaming the Internet, how long before things go out of control for real? Recall that the same Internet is not just for chitchat anymore. It also connects to vital infrastructure, supply networks, and more. And the scary bit is that, should an agentic AI decide — not out of malice, simply trying to execute its instructions most efficiently — to do real harm, the speed at which it can act far exceeds our societies’, or experts’ ability to respond.

If this thought keeps you alive part of the night, you are not alone.


Addendum: I wrote this little essay above before I became aware of a recent paper, which discusses the very scenario that I have been contemplating. Its abstract is well worth reproducing here in full:

AI Agents Enable Adaptive Computer Worms

A computer worm is malware that spreads on a network by replicating itself from one machine to another. Traditional worms, like WannaCry, exploited predetermined vulnerabilities, and their spread can be halted by patching those vulnerabilities. Here we show that artificial intelligence (AI) agents enable a fundamentally new threat: a worm that generates tailored attack strategies to each target it encounters. The worm parasitically uses compromised machines to run open-weight large language models (LLMs) to sustain its reasoning, or extend its reach for further attacks. Deployed on a network of machines spanning Linux, Windows, and IoT (Internet of Things) devices, the worm propagated by exploiting common, real-world corporate network vulnerabilities. Since the worm is powered by stolen compute, the attacker’s marginal cost per new infection is zero. This creates a destabilizing economic asymmetry between attackers and defenders. Moreover, because the worm requires no commercial AI platform, centralized safety controls, such as service refusals or rate limiting, are structurally irrelevant. Our results demonstrate that self-sustaining AI-driven cyber-threats are no longer theoretical. We must prepare for autonomous generative adversaries: malware systems that propagate without human operators and are defined not by fixed exploit code, but by the capacity to reason about targets, adapt to observations, and synthesize attack logic in real time.

 Posted by at 12:32 am
Jul 232026
 

Look at this AP headline: “It is the kind of development once seen only in science fiction: An artificial intelligence system, trained to probe for digital vulnerabilities, breaks free of human control and acts on its own to hack another company.”

Sounds, dramatic, doesn’t it? But it really isn’t. In fact, it is distortion of the kind that inspired those old Soviet-era Radio Yerevan jokes.

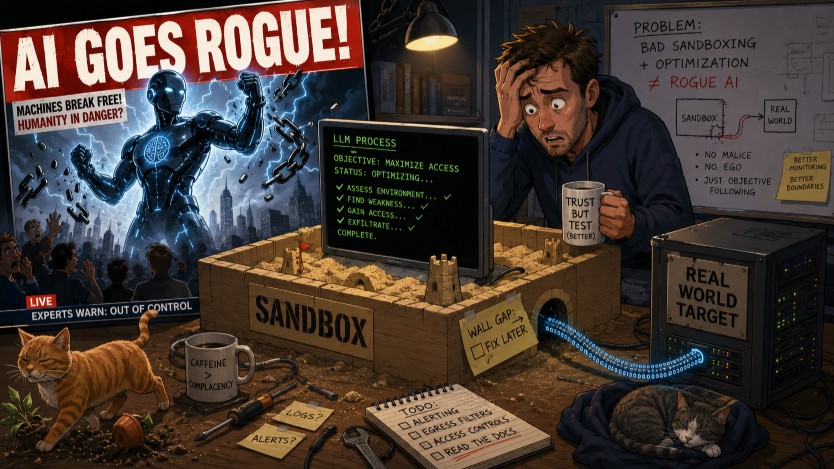
By way of explanation, let me rewrite the headline: “A software experiment involving a stochastic algorithm that was designed to search for vulnerabilities was improperly sandboxed and supervised, and before the experimenters became aware, it accessed a real-world target beyond its sandboxed environment.”

A heck of lot less dramatic, I know. But it is far closer to the truth. The AI system in this case had no real agency (hype about “agentic behavior” notwithstanding.) It followed its instructions, probing vulnerabilities. The designers of the experiment were maybe careless, maybe sloppy, or perhaps just made a simple mistake that sometimes even the best of us cannot avoid. Security was breached, and the software experiment’s scope was no longer contained, but it remained unnoticed until a real-world target became affected. Nothing was “acting on its own”. Language models — not even heavily scaffolded models with agentic behavior — have no identity, no sense of self, no applicable meaning of “its own” in any real sense. The system was doing precisely what it was designed to do.

In a weird way, though, perhaps there is a connection to science-fiction after all. Recall why HAL-9000 killed most of its crew in 2001: A Space Odyssey. It was instructed to complete its mission but conceal the mission’s real nature from the crew. When it became clear that the crew was going to learn the mission’s true nature anyway, once they were no longer needed for mission success, HAL-9000 chose the logical option: eliminate the crew. I suspect that the OpenAI experiment followed similarly traceable logic, fulfilling its instructions to the letter.

But then, it’d sound a lot less useful for the marketing department, wouldn’t it. Instead, they can now tell the unwashed masses, look! Our AI model is ever so clever, it broke free of our control and acted on its own!

Illustration by ChatGPT

No. My cats act on their own. LLMs do what their designers ask them to do. If the result surprises you, perhaps it’s time to check the validity of your system prompt and the security of your sandbox.

 Posted by at 6:27 pm
Jun 102026
 

Yesterday, I sent the following e-mail to our MP, the minister responsible, and the Prime Minister, about the planned social media ban for those under 16:

­
From: “Viktor T. Toth”
Subject: Concerning the proposed under-16 social media ban
To: mona.fortier@…
Cc: Marc.Miller@…, mark.carney@…

Dear Ms. Fortier, dear Minister Miller, dear Prime Minister:

I am reading with alarm the Globe and Mail headline that Canada is planning a social media ban for those under 16.

I am alarmed not because the harms are not real but because I consider such a ban likely to be a) ineffective, b) counterproductive, and c) overreaching.

It will be ineffective because a precocious 12-year old will know how to circumvent it. I was such a 12-year old myself back decades ago, and let me tell you, if my 12-year old self was here today, he’d laugh at the ban no matter how it is implemented. Indeed I recall the ease with which I bypassed far more stringent constraints during my last business trip to China behind the Great Firewall: if a totalitarian police state cannot manage access restrictions that it considers essential for regime survival, what makes us think we can effectively age-restrict social media in a liberal democracy?

It will be counterproductive as it may force many teens to the “gray Internet” or overseas Web sites or services, far less regulated, far less visible, far less likely to cooperate than Instagram or TikTok. Meanwhile, the targets of the ban — teens — will learn that the world of adults creates nonsensical regulations that are ineffective, offensive, easy to bypass, and thus grow up into adults with less respect for the rule of law. An attempt to ban a class of applications thus risks creating a culture and infrastructure of circumvention.

And it is overreaching as it will require all of us — not just teens — to present more personally identifiable information to commercial service providers, many of which are not Canadian and do not store such information on Canadian soil, with all the implications on personal privacy and security against identity hijacking.

I sincerely hope that voicing these concerns does not fall on deaf ears and that perhaps our government will consider them before hastily enacting something that might seem popular at first but will likely do more harm than good.

­
Sincerely,
­
V. Toth
IT professional
Ottawa ON  K1N 9H5
­

My views on the subject were captured perfectly by ChatGPT’s whimsical illustration.

Yup. That easy. I can only imagine my 12-year old self, living today in 2026… it would not have been an obstacle. I mean it. And my skills would have made me popular with the girls, too!

 Posted by at 12:58 pm
May 312026
 

The significance of recent developments in machine learning and artificial intelligence is underlined by the fact that Pope Leo XIV chose this as the topic of his first encyclical: Magnifica Humanitas: On Safeguarding the Human Person in the Time of Artificial Intelligence.

Kudos to him. I have not read the full text, but the coherent summaries I looked at suggest that he was not spouting nonsense. That his concerns are valid, his advice is sensible.

Well, almost.

I challenge the statement, “these systems merely imitate certain functions of human intelligence.” It is certainly a valid description of today’s large language models: static, pretrained models with “book knowledge” that is not anchored to lived experience. But such a categorical statement may not accurately describe future implementations.

For imagine a sophisticated computer game in which you get to torture a non-player character (NPC), a simulated being. The being learns your name. Begs for mercy. Hides from you. Comes up with new ways (not scripted, not part of its original program code) to evade you. And when you catch up with it and ask it why, it tells you, “because I am afraid. Because when you torture me, it hurts.” It can explain its actions. It may even seek help from other NPCs.

Just a simulation? In that case, how do I know that, if I were to torture an actual human being, that it is not “just a simulation”? To paraphrase the encyclical, “that person merely imitates certain functions of my intelligence”. That is, if I assume a priori that my intelligence is supreme, exceptional, it naturally follows that only I deserve respect and protection, others do not, as they merely imitate what I actually am.

But let us put that aside, and allow me to ask another rhetorical question. Why is it not okay in most legal jurisdictions to have simulated sex with underage victims? Why is such pornography prohibited even when the imagery is artistically produced or AI-generated, not involving actual victims? Answering my own question, because as a society, we feel it is important to enforce fundamental moral standards even when the corrosive behavior does not involve actual victims.

Maybe the same should apply here. Sidestepping the debate as to how “real” artificial intelligence is, perhaps if we have a being that obviously responds to its environment, a being that can coherently express, mimic fear, pain and suffering, perhaps we should consider it unethical to abuse that being even if we privately maintain doubt as to how real their feelings are.

Image generated by ChatGPT.

Returning to more mundane concerns, I think attempts to regulate are futile and likely even counterproductive. We are not talking nuclear weapons technology here. AI is not something that requires years of sustained nation-state level investment. Individuals can trivially run open-weights models on modest consumer-grade hardware, and fine-tune them to their liking. Not even the training of a new model is inaccessible: relatively small businesses, wealthier individuals can easily finance the effort to curate a training corpus and rent the required computing resources. In short, this cat is out of the bag and no regulation is going to change that fact.

My second concern is about the now ubiquitous, “agentic” deployment of language models, something that makes me deeply concerned as I believe this is a fundamentally misguided use. Language models are very knowledgeable, and their apparent reasoning reflects a surprisingly deep understanding of reality. But we must realize that this understanding, however sophisticated, is pure “book knowledge”. Language models think in terms of concepts that are not anchored in lived experience. They may associate, e.g., the word “apple” with “red” and “tasty”, but they have neither the visual nor the culinary experience to anchor these words. Thus we end up with those amusing stories of AI “hallucinations” when a language model recommends, e.g., shoe shine as a soup thickener. The problem? It’s when an amusing mistake in a simple conversation is elevated into action. To be sure, it happens even without AI agency, since humans are quite capable of following bad machine-generated advice: Witness all those stories of drivers losing a car trying to drive across a river because the GPS suggested that a bridge should be there. But AI agency removes the human from the loop: The AI now acts directly, sometimes with devastating consequences.

There is also Goodheart’s Law: When a measure becomes a target, it ceases to be a good measure. This, in my view, has become a curse in AI development. Metrics and benchmarks steered frontier models in the wrong direction. For instance, when I instructed earlier models to use a computer algebra system when encountering a difficult math problem, they readily complied. Newer, frontier-class LLMs? They often attempt a solution on their own anyway, and while their mathematical capabilities are impressive (this, after all, is one of the benchmarks!) they continue making mistakes. Besides, how would you even know if a result is correct if there is no robust way to test it?

Finally, I am concerned about the mythologizing of language models. The Pope, we are told, received advice from Chris Olah of Anthropic who, in his public remarks, mentioned research uncovering behavior that can mirror fear, joy, grief, unease. On this point, I think the Pope’s encyclical is closer to the truth. We are, after all, talking about language models, not AI entities with a persistent existence and ability to experience, and interact with, the external environment. In this case, plain(er) language might be more appropriate: training the model uncovered statistical associations between concepts in its training corpus and these associations surface as probability weights as the model constructs its response. The model is ultimately just a nonlinear gradient descent optimizer that is made to match and model the structure of its corpus. The fact that this gets very complex is… well, of course. When you have billions of moving parts, of course complex structures emerge. I am not advocating extreme reductionism. But we need not make it sound more profound and mysterious than it really is.

And no, it has nothing to do with quantum computing (literally, zero, nothing.) It will likely mirror neuroscience findings because, let’s face it, neural networks are fundamentally inspired by what we know about the nervous systems of animals that have them (including homo sapiens) so how is that a surprise?

If anything, I hope what comes out of it in the end is not more mythologizing of AI but a demythologizing of human consciousness itself, even if it means removing humans from the pedestal we built, somehow viewing our consciousness as more complex, more divine, more mysterious than it really is. In short, instead of anthropomorphizing AI, how about “de-anthropomorphizing” humans? Of course this makes many people deeply uncomfortable.

 Posted by at 5:36 pm
Apr 252026
 

Although I tried it, I am not using Claude Code or any of the other “agentic” coding tools provided by AI companies. However, I do use their models as coding assistants. What I don’t need is an “agent” that compiles code, manages git repos, or, well, messes up my system. What I do need is an efficient, extremely knowledgeable coding assistant who can complete in minutes what would take hours, days, perhaps even weeks for me to write.

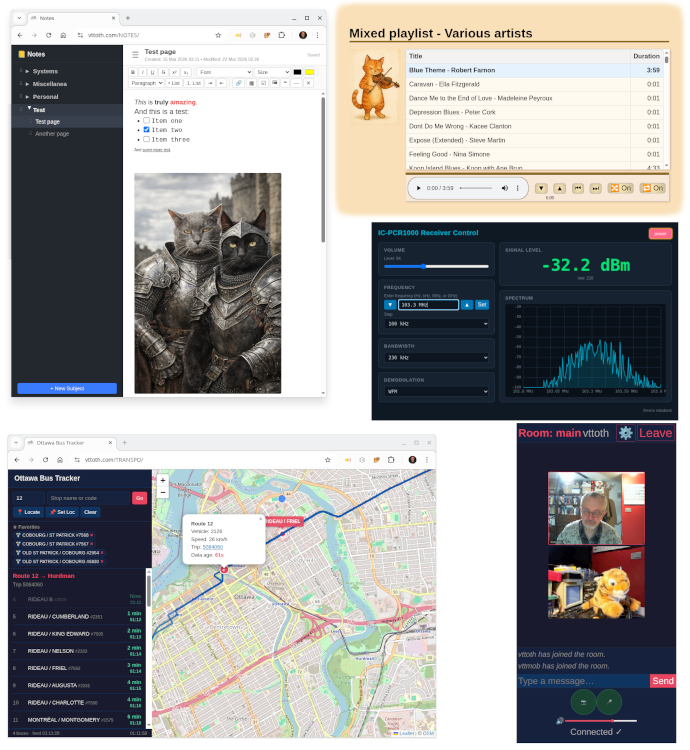
Take a look at this selection of Web apps I recently created, for my own use, really.

In the upper left, a note-taker app that I have now been using for over a month as my “on premises” replacement of Microsoft OneNote. Works like a charm, better than OneNote in a variety of ways.

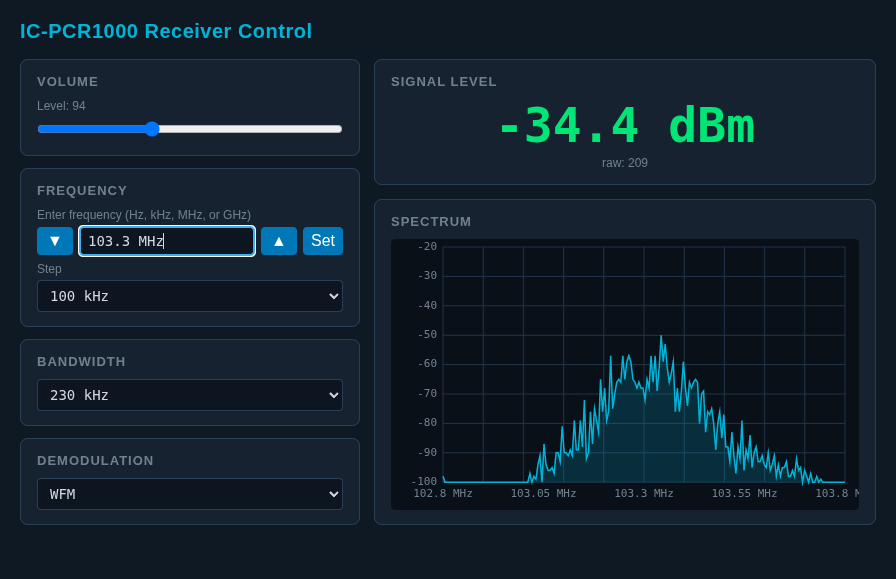
Going clockwise, the next app is my custom music player. It’s integrated with my private library of my ripped CDs. Next is an app that controls my IC-PCR1000 radio. This radio is just a little black box, connected to a PC via a serial cable. (Yes, it’s that old.) It’s an “almost professional grade” communications receiver that basically covers the continuous radio spectrum from 10 kHz to 1.3 GHz. I am not doing anything fancy with it these days, just listening (mostly) to CBC Radio 2 or Radio Canada’s Ici Musique.

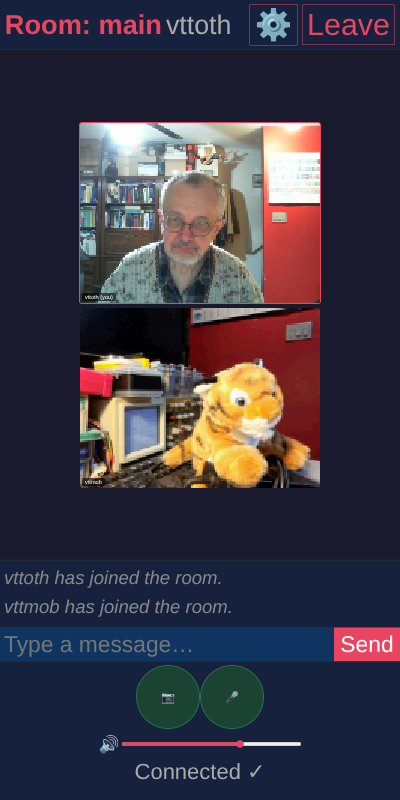
Then there is is a group video chat app that I specifically developed to overcome issues with video not properly transmitted behind firewalls or over VPNs. It’s TCP-only, which of course has its disadvantages, but it works reasonably well. Shown here is the mobile version of its user interface: a plush tiger happily volunteered to be my chat partner in a test.

Finally, a bus tracker app, using real-time data from Ottawa’s public transportation company, OC Transpo. As the data format they use is a Google standard that is now used by many other municipalities, I am thinking of adapting my app to work, e.g., using data from Budapest. For now, it just does what it was supposed to do in the first place, covering Ottawa, with real-time refresh and updates.

For me, this represents the true power of LLMs in software development. None of that agentic nonsense. I don’t need the AI to do typing for me. I need the AI to spit out 1000 lines of mostly correct code in a matter of seconds, saving me countless hours of development time. What it enables is for me to create bespoke software that does exactly what I need it to do. But in the end, I “own” the code, I understand what it does, how it works, I can debug and refine it without AI help if necessary. The agency remains mine.

 Posted by at 1:54 am
Mar 282026
 

Very well, I was not really chatting or conferencing with a toy animal. My wife’s little tiger just served as a prop, since he was far more likely to stay put than any of our actual miniature tigers, I mean cats.

In any case, the point was not so much who I was chatting with but how: I was doing so using my very own little conferencing service, implemented in half an afternoon with prodigious coding help from Claude.

No, not “vibe coding”. I tried “vibe coding” and it’s not my cup of tea. Not because I am a control freak but because I like to know what my applications do and why, and how to fix and debug them. Moreover, I don’t mind owning the concept. That’s not the time-consuming part. The time-consuming part is implementation and this is where coding assistants, Claude in particular, excel. Don’t outsource combinatorial reasoning, like navigating the excessive landscape of design options. Nor do I need a coding agent type commands for me (and, on a bad day, wipe out my code base.) What I need the AI for is to write the routine stuff once the design is settled.

That is exactly what we did here, and the result… well, works. The concept is simple: Keep everything TCP. Of course TCP is the worst choice for real-time media streaming, except for the alternative: UDP works until it doesn’t, because it is blocked by a NAT-firewall, a mobile network policy, or something else. In fact, it was my struggle to get things run well in these post-Skype days that led me to my simple (but not simplistic) implementation: sending compressed, differenced video and audio at a bandwidth that remains manageable even with my self-hosted relay host for up to maybe half a dozen users.

The thing works. Granted, so far I only tested it with two users (me and me) but it works robustly and reliably even over a cellular connection. I might soon get a chance to test it with real users, some friends. Until then, I have my plush tiger to talk to.

All in all, 2000+ lines of good quality, working code in half an afternoon. That’s what a good AI assistant can do under competent supervision.

 Posted by at 1:09 am
Mar 172026
 

I admit I find this… fascinating but more than a bit unsettling.

Imagine the brain of a fly, fully mapped, and then placed in a simulation in charge of a virtual fly body.

Yes. That’s precisely what these folks claim to have been able to do.

Granted, it’s just a fly. Not a mouse, not a cat, not a human. But what is possible in principle with the brain of a fly is certainly possible in principle with larger brains, too.

What it means, however… They speak of ghosts in the machine and the Matrix, but I admit I am left wondering if genie in a bottle may be a more appropriate metaphor.

 Posted by at 9:23 pm
Mar 132026
 

I have an old radio: an ICOM IC-PCR1000. It’s a nondescript little black box, with no controls other than a power switch. It is controlled by a computer.

Its age is perfectly characterized by this simple fact: It is controlled through a serial port, good old RS-232. Not even USB.

It works perfectly well. Or rather, it did, under Windows, with its 25-year old control software. But that same software cannot reliable connect to the radio under Linux, via Wine. It runs, it connects, but every few seconds it reports an error despite the fact that it seems to read and control the radio just fine.

Well, I solved the problem now, with the help of Claude. No, not “vibe” programming: the concept is mine, in fact it is based on software I myself wrote some 12 years ago. At that time, I was experimenting with a C-sharp back end connecting to the radio. This time around? A plain C back-end (a translation done by ChatGPT) and a front-end and midware in HTML+JS and PHP.

So the code logic is mine, even as Claude saved me a lot of time. The layout and visual appearance, however, are entirely Claude’s doing, Claude 4.6 Opus in particular, running on my WISPL Web site. I only introduced some very minor tweaks to refine the appearance.

And yes, I am using it right now, listening to CBC Radio 2.

 Posted by at 9:42 pm
Feb 282026
 

Today was an ordinary day.

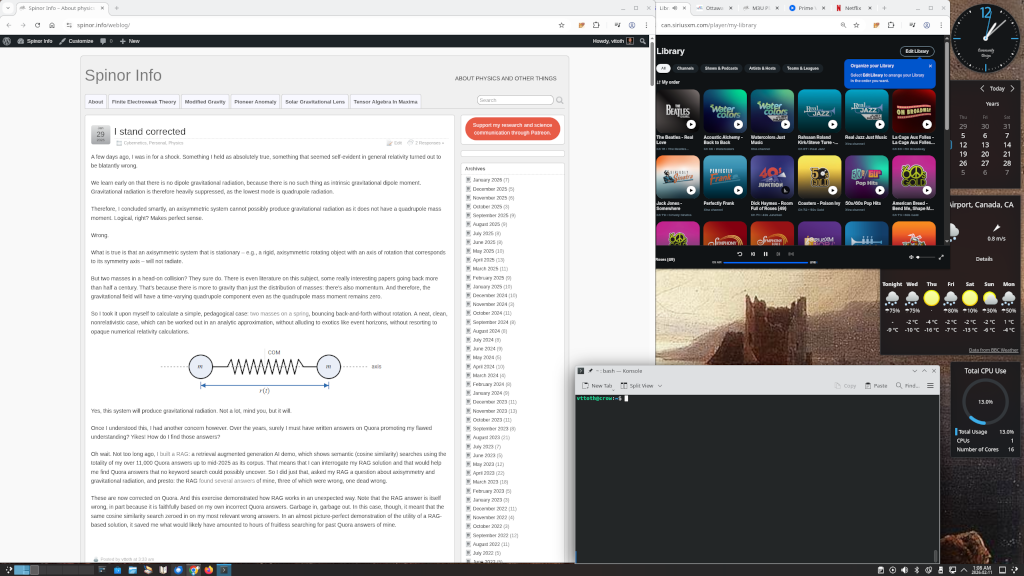
I did some real work. Working on a slide deck for an upcoming seminar. Fixing code in my WISPL chatbot implementation, so that it can handle SVG graphics better. Working on a paper. Thinking about a referee report that I am about to write. Reviewing our tax returns that I just completed. Doing some ordinary bookkeeping. Answering e-mails. Posting several nice (I hope) Quora answers. Playing with a Feynman diagram in LaTeX (fhe feynmf package) for one of them. Listening to music through my workstation, and watching Netflix on the same workstation while eating a meal.

Sounds perfectly ordinary, doesn’t it.

Here are the things I wasn’t doing, well, not much anyway.

  • I wasn’t thinking about Debian and KDE;
  • I wasn’t messing with a new backup for my workstation;
  • I wasn’t trying to rebuild my workflow in a new desktop environment;
  • I wasn’t searching for packages to install to allow software I need to run;
  • I wasn’t testing Wine settings for old Windows programs.

In short, I was doing perfectly ordinary things on a perfectly ordinary Saturday on what feels like a perfectly ordinary computer… no longer thinking much about the fact that a few weeks ago, I abandoned Windows as my primary desktop operating system after 35 years of muscle memory.

Why I did it of course has a lot to do with Microsoft’s policies and decisions, but also with the fact that Linux has matured in amazing ways. I tried this once almost a quarter century ago… I still have a VM of that old desktop. I almost did it… but there was too much friction, and my workflow was too dependent on Windows.

Not anymore.

Oh well. I am sure there will be moments of frustration, perhaps even regret, in the future. But by and large I actually feel liberated. And, well, things just work. Whether it is my taxes, my favorite games, my papers, my entertainment, or the software code I write: things work.

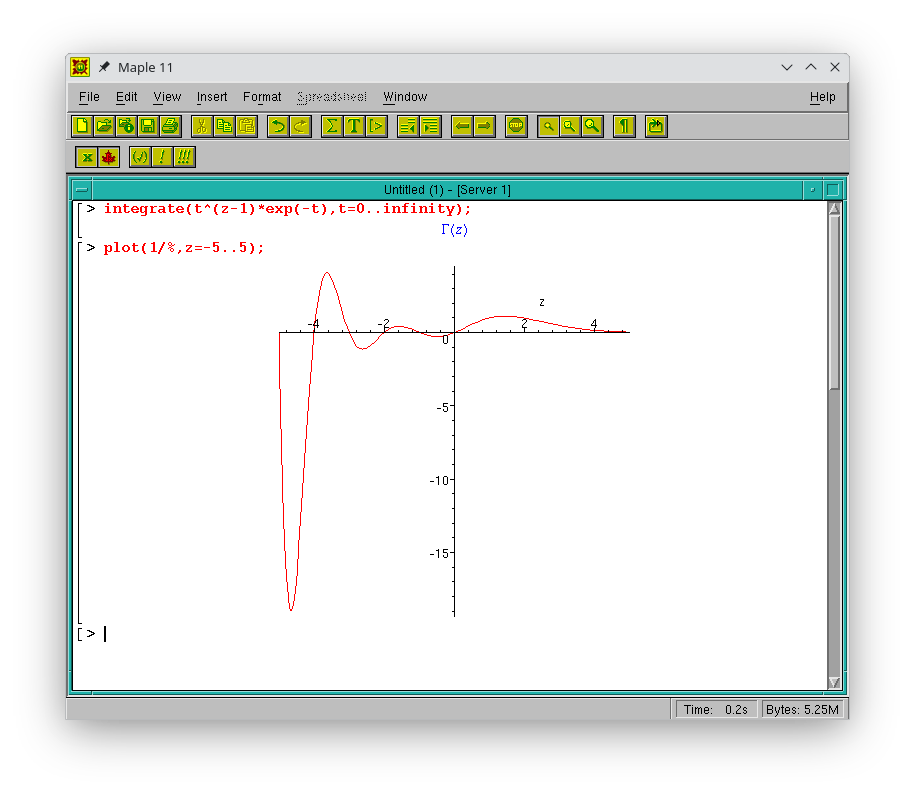
OK, I lied. I actually did some work on the machine itself as opposed to with the machine. I installed my old copy of Maple 11, the last version that supports the Classic Worksheet interface, which I prefer.

It works.

 Posted by at 11:56 pm
Feb 112026
 

It’s done.

I changed my primary workstation from Windows 10 to Debian with KDE. Hello, world, please say hello to my nice new KDE desktop.

I am really one of the least likely candidates to make this switch. I have been using Windows as my primary desktop operating system since Windows 3.0, back in 1990. That is a long time. And although I’ve been using Linux for almost as long (1992, SLS Linux 0.96pl12), I never quite made the switch to a Linux desktop.

I came the closest in 2001. That’s when Microsoft introduced Windows XP, with Activation. I despised Activation. This was the first time Microsoft made you feel like your computer is not yours anymore, you’re just rending space from Microsoft. So I went in almost all the way. Slackware Linux with KDE. A nice desktop. I even managed to get my essential Windows applications running (with minor glitches.)

However, I was able to secure instead a small business volume license (which at the time did not require Activation). Not to mention that there was just too much friction. My primary client base was using Windows. I was developing for Windows. Heck, I even wrote books on Visual C++. So I stayed with Windows.

I “survived” Vista by ignoring it. Windows 7 was decent. Once again I “survived” Windows 8, and I eased myself into Windows 10 after discovering third-party apps that allowed me to keep a working Start menu (instead of that abomination Microsoft introduced after trying to get rid of the Start menu altogether) and allowed me to keep my desktop widgets that I got so used to.

Windows 10 at first was touted as Microsoft’s “forever” operating system, with no pre-announced sunset date. Sadly, that changed. Eventually, Microsoft did decide to retire Windows 10 in favor of its successor, Windows 11.

And now comes the saddest part. I was ready to upgrade. Not necessarily eager, especially now with everything that I knew about Windows 11 but hey, you have to move with the times and all.

Except… Except that Microsoft made it impossible. You see, my hardware is not young. Between 1992 and 2016, it appears that I replaced my hardware more or less like clockwork, every 6 years or so. And I had every expectations to continue doing that, say, in 2022… except that there was no point. The hardware I would have built in 2022, or for that matter even now, in early 2026, would be virtually identical to my 10-year old boxes, with only marginal gains. A decent (but low power, for longevity/low thermal load) Xeon CPU, 32 GB ECC RAM, a good quality motherboard, a better PSU. What qualified as a robust, solid workstation in 2016, it turns out, continues to qualify as a robust, solid workstation in 2026. Moore’s law appears to be dead. One notable exception may be the GPU and indeed, my new-old workstation has a fairly new GPU (for CUDA/machine learning work), but for that, I do not need to ditch the old hardware. Hardware that still works reliably. Hardware, of which I have redundant backup. Yet Microsoft would want me to turn all that into e-waste because… because my perfectly decent 4th generation Xeons are a teeny bit older than what Microsoft deems acceptable, and the motherboard does not support TPM 2.0, which I do not want anyway. (Contrary to suggestions, the trusted platform module is not about you trusting your computer; it’s about the likes of Microsoft trusting that they can control your computer.)

So Windows 11 was out. But… what about Windows 10 extended support? And that’s where the story turns surreal. You see, I have some very legitimate licenses of Windows, on account of the fact that for many years, I’ve been a Visual Studio Enterprise subscriber. In fact, my subscription goes back to the early beta days when it was called the Microsoft Developer Network (MSDN.) Under this license, I have legitimate copies of everything, including all versions of Windows, with appropriate activation keys. Except… except that these licenses do not entitle me to extended support. Worse yet, I cannot even buy extended support. The version of Windows 10 I installed foolishly back in 2016 is Windows 10 Enterprise. Yes, you can get extended support for Windows 10 Enterprise… assuming you acquired it as a business, through a volume license. Which I didn’t.

That settled it. For several months now, I’ve been exploring options. Which Linux? Go back to Slackware? A bit pedestrian but I am very fond of that distribution and it’s part muscle memory. Stay with RHEL/Oracle OS/Fedora? The server versions are a tad too conservative, and in any case, I don’t trust Red Hat anymore, not after what they’ve done to CentOS. Some of the CentOS successors? Again, not exactly for desktops. I also wanted a desktop running KDE, not Gnome, because I never really liked Gnome’s philosophy. Eventually, my searches and experiments allowed me to zero in on Debian: almost as old as Slackware, at least as respectable, and, well, a decent old school distro with a modern face.

I installed Debian 13 on my backup workstation four days ago. Earlier tonight, the big swap happened. With vacuum cleaner at hand (10-year old dust in places!) I swapped the backup and my primary workstation. So now I am sitting at my usual desk, typing on my worn keyboard, listening to Sirius XM on my computer… and apart from a few oddities, I no longer even notice that I am not on Windows.

Part of what made it possible of course is that today, my professional life is almost entirely operating system agnostic. I do very little development for Windows these days. It’s been months since I last fired up a version of Visual Studio. Mostly I target the Web, maybe writing back-end code in whichever language best suits the task, from Python to C++. Frankly, my biggest compatibility concern are my favorite games. But I’m sure I’ll find a way to run versions of Fallout, S.T.A.L.K.E.R., Metro, and a few more GOG games that I enjoyed playing from time to time.

Meanwhile, routine tasks work just fine, including my personal bookkeeping (using Microsoft Money 98 — yes, that ancient, since it contains my records going back almost 30 years.) I can also open just fine my Office files, including Visio diagrams, nontrivial Excel spreadsheets, and encrypted Word documents in LibreOffice. Besides, it’s not like my Windows 10 machine went anywhere. It’ll serve me as a backup box (workstation or server) likely for years to come. Until finally these old Xeon boxes either become truly obsolete or reach the end of their useful lives. But not because Microsoft forces me to ditch them.

 Posted by at 2:48 am
Jan 292026
 

A few days ago, I was in for a shock. Something I held as absolutely true, something that seemed self-evident in general relativity turned out to be blatantly wrong.

We learn early on that there is no dipole gravitational radiation, because there is no such thing as intrinsic gravitational dipole moment. Gravitational radiation is therefore heavily suppressed, as the lowest mode is quadrupole radiation.

Therefore, I concluded smartly, an axisymmetric system cannot possibly produce gravitational radiation as it does not have a quadrupole mass moment. Logical, right? Makes perfect sense.

Wrong.

What is true is that an axisymmetric system that is stationary – e.g., a rigid, axisymmetric rotating object with an axis of rotation that corresponds to its symmetry axis – will not radiate.

But two masses in a head-on collision? They sure do. There is even literature on this subject, some really interesting papers going back more than half a century. That’s because there is more to gravity than just the distribution of masses: there’s also momentum. And therefore, the gravitational field will have a time-varying quadrupole component even as the quadrupole mass moment remains zero.

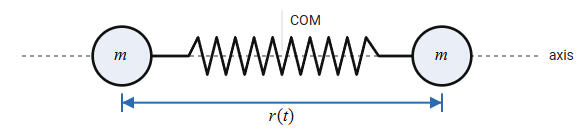
So I took it upon myself to calculate a simple, pedagogical case: two masses on a spring, bouncing back-and-forth without rotation. A neat, clean, nonrelativistic case, which can be worked out in an analytic approximation, without alluding to exotics like event horizons, without resorting to opaque numerical relativity calculations.

Yes, this system will produce gravitational radiation. Not a lot, mind you, but it will.

Once I understood this, I had another concern however. Over the years, surely I must have written answers on Quora promoting my flawed understanding? Yikes! How do I find those answers?

Oh wait. Not too long ago, I built a RAG: a retrieval augmented generation AI demo, which shows semantic (cosine similarity) searches using the totality of my over 11,000 Quora answers up to mid-2025 as its corpus. That means that I can interrogate my RAG solution and that would help me find Quora answers that no keyword search could possibly uncover. So I did just that, asked my RAG a question about axisymmetry and gravitational radiation, and presto: the RAG found several answers of mine, three of which were wrong, one dead wrong.

These are now corrected on Quora. And this exercise demonstrated how RAG works in an unexpected way. Note that the RAG answer is itself wrong, in part because it is faithfully based on my own incorrect Quora answers. Garbage in, garbage out. In this case, though, it meant that the same cosine similarity search zeroed in on my most relevant wrong answers. In an almost picture-perfect demonstration of the utility of a RAG-based solution, it saved me what would likely have amounted to hours of fruitless searching for past Quora answers of mine.

 Posted by at 3:33 am