Nov 012026
 

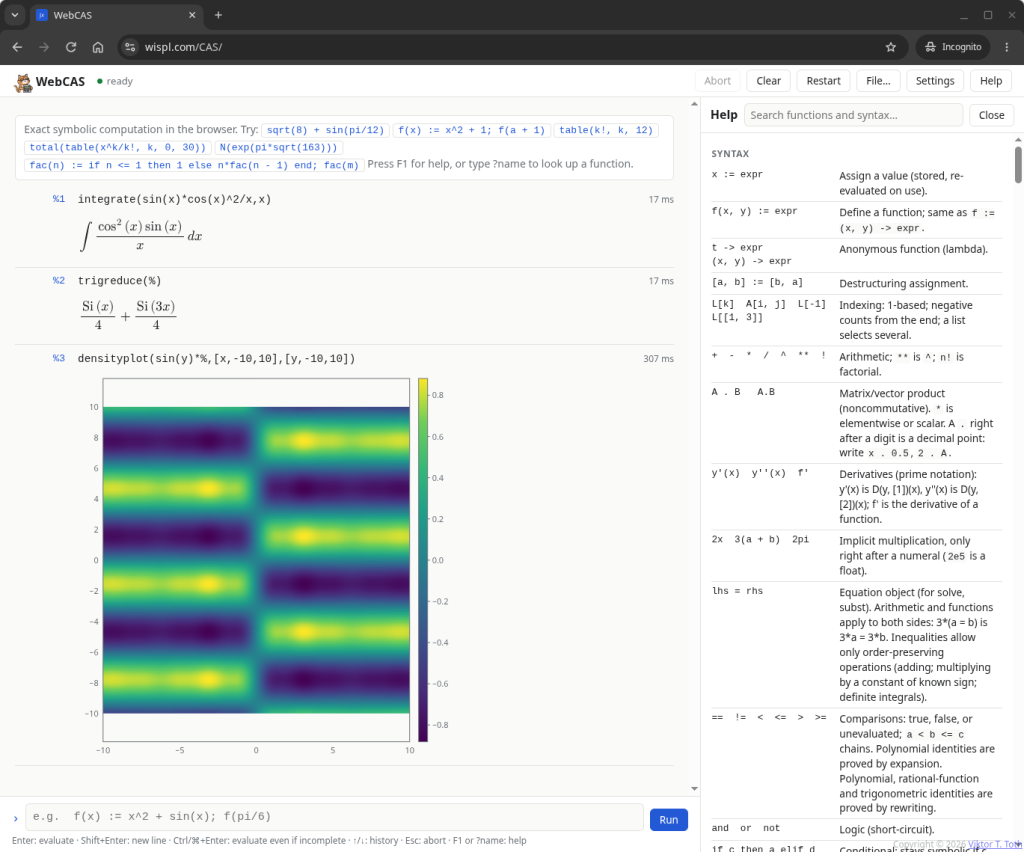
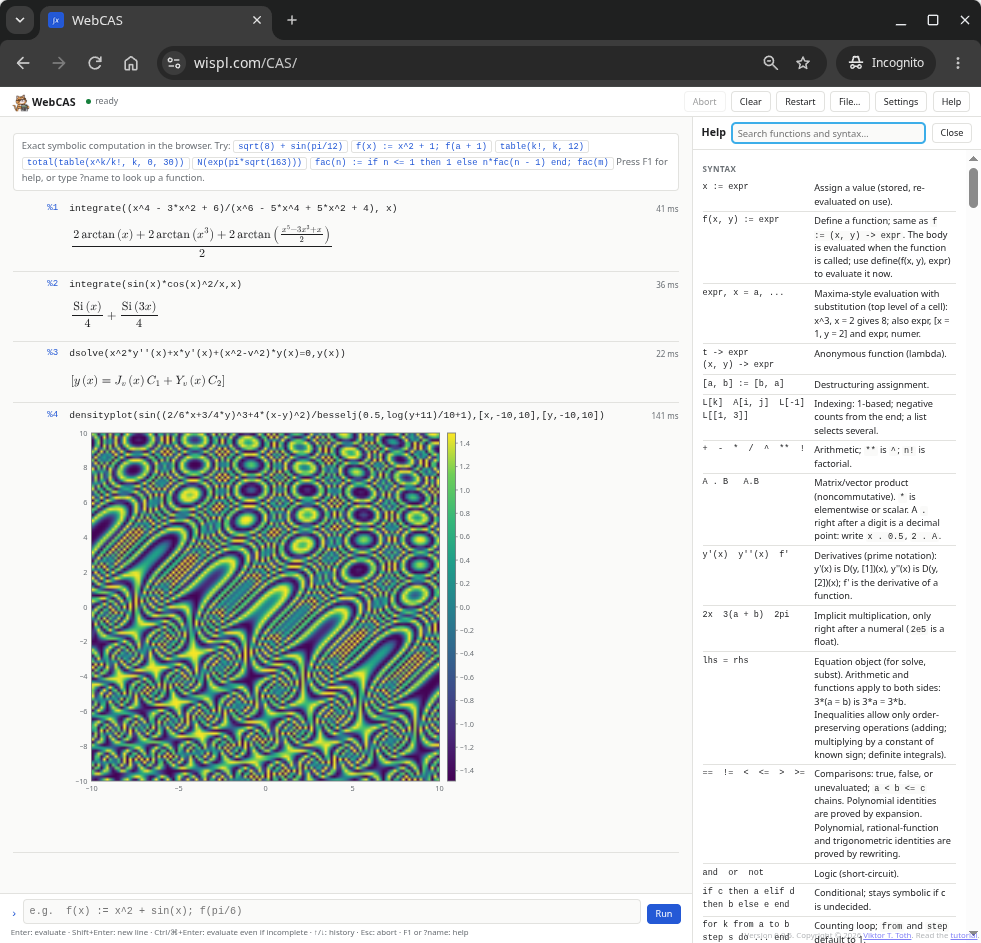
I keep playing with my brand new creation, this Web-based computer algebra tool. One day, I’ll likely add some 3D plotting but for now, I am being fascinated by some density plots.

Anyhow, since we’re at it, I also included some nontrivial integrals and a second order differential equation, for fun. Yes, it can do that all.

 Posted by at 11:50 pm
Oct 272026
 

A few days ago, I exchanged some e-mails with a fellow volunteer Maxima developer. That exchange reminded me of a pet project of mine, something I’ve been contemplating for quite some time: a computer algebra system, one significantly less ambitious than a frontier-class system like Mathematica, Maple or, I dare include it in that list, Maxima, but one that runs in the browser, with no server-side code and nothing to install on the user’s computer either.

This time around, I decided to test my idea with Claude Opus 5.5, their latest and greatest model. I outlined my ambition in a couple of paragraphs. The result was less than overwhelming: After some 20 minutes, Claude ran out of “thinking” tokens, and returned nothing other than 128,000 tokens wasted.

Never mind, I figured, let’s try it again, with a slightly refined prompt to ensure that Claude doesn’t embark on a project bigger than itself. And that, well, worked. Claude presented a plan and then, following my instructions and my replies to its questions, began to proceed with the implementation one step at a time.

In this past, this is usually where things got derailed. Sometimes, the model got too ambitious and ran into token limits. Sometimes, the model’s code was incoherent, self-contradictory. Sometimes, the initial code was working, more-or-less, but additions did not.

But not this time. Claude kept churning out sensible code and, most notably, starting at the very first stage, included a testsuite. So even though we had no usable system yet, the testsuite was an assurance that the code we’re building is doing what it was supposed to do.

Notice that I am not using Claude as an “agent”. I did not give it carte blanche in a folder of its own, to build code, download libraries, mess around. No. Claude was talking to me. It was then I who decided if the code Claude presented was good enough or not, it was I who incorporated it into the code base. Claude, accordingly, provided helpful, detailed explanations at each stage. The important point is that the role I retained was that of a senior programmer who may delegate subtasks to junior programmers, but retains overall control of the project at a technical level.

And Claude delivered beyond expectations. Soon, I found myself hooked. One module after another, which I added, tested, tried. A rather nice-looking application was beginning to take shape. And there was both breadth and depth: the application was already acquiring features more sophisticated than I ever dared to plan for, while at the same time Claude never forgot to deal with the mundane, such as appropriate visual representation via MathJax or a growing collection of sections in interactive help.

About halfway through the project we got to basic calculus. I was beginning to wonder: When will Claude falter? When will useful code give way to AI hallucinations, code referencing non-existent language features or capabilities? But none of that happened. Claude robustly, methodically implemented basic calculus, one subroutine at a time.
Again, I stress, Claude had no free reign. We were proceeding step by step, I took the code Claude wrote, integrated it into the application, scrutinized it when I had to, looked for testsuite failures, even corrected the trivial ones.

Once we got past linear algebra and multivariate equations, I decided to get really greedy. I asked Claude, can we do ODEs and PDEs? Because even a half-decent differential equation solver makes a world of a difference when it comes to the usability of a CAS. Claude accordingly revised our plan, and then did the grunt work.

Claude remained enthusiastic throughout, but I began to notice that its responses felt… a little less coherent. Nothing big, no real mistakes, just subtle things like harder-to-understand explanations or instructions on where to place a code patch. No wonder: we were by now around 700,000 input tokens per conversational turn, rapidly approaching Claude’s 1 million token limit. (I also noticed the increasing frequency at which I received notifications from Anthropic about additional credit card charges. But, I digress.)

Claude was still eager to proceed with more ambitious additions but I asked it for something else: something genuinely useful in a CAS, a broader class of special functions like hypergeometric functions or Lambert’s W function. Claude delivered.

So roughly 36 hours after I sent my first prompt to Claude, I was in possession of a full-featured, rich, eminently capable browser-based computer algebra application. One that can also be installed on an Android device as an offline computer algebra tool.

This has been an amazing experience. Was it “vibe coding”? I don’t think so. I was not just playing the dumb user, asking the agentic AI to deliver a solution. I was a senior partner with an incredibly capable, knowledgeable junior assistant, but I retained intellectual ownership of the result, indeed I can confidently edit, and fix/expand the code myself when I have to, since I understand what it does.

End result: 26,412 code lines in 163 files, at the cost of 31,006,699 input tokens and 3,048,131 output tokens, consumed over the course of less than two days. And WebCAS — the name picked by Claude — is already my favorite computer algebra application, one that will likely receive regular updates frmo me in the future.
 Posted by at 10:38 pm
Oct 232026
 

I use AI on a daily basis, in my software development work. It is an incredible productivity tool. Things that would take days, even weeks, are often accomplished in mere minutes.

Take this example, just the other day. I received another dire warning from Google, indicating that their existing search services for third-party software will be discontinued. This was bad news: My own WISPL chatbot uses Google’s search API and the snippets it provides as a means for AI models to search the Internet for accurate or up-to-date information. This capability will no longer be available starting in January.

So I consulted with, well, Google. What are the alternatives? Google’s own AI helpfully recommended several, among them a service called Brave Search. I checked it out and it seemed to match my needs perfectly, in fact better than Google ever did. So… let’s do this! I rolled up my sleeves and… fired up Claude in my chatbot, presented the problem, presented the code segments from my chatbot implementation that would likely be affected, and asked Claude to suggest a solution.

In a minute, I had a response from Claude. A nice new function that would connect to Brave Search. A thin compatibility layer that allows my code to use wither Google or Brave. Even a bug fix for something it stumbled across as it reviewed my old code.

I took Claude’s code, incorporated it into the source base, made some minor adjustments, ran some tests and that was it. Less than three hours after I began this exercise, the solution was deployed. Brave Search works perfectly in my WISPL chatbot, and delivers better results than Google ever did, suitable for AI models to digest.

But… notice what I did not do as part of this exercise. At no point did Claude have access to my source code. I was using Claude strictly as a chatbot. I received its output as a recommendation, not as a solution. I scrutinized it, evaluated it, adjusted it, and then integrated it. As a result, by the time I was done, I “owned” the code, figuratively speaking. I know what it is, where it is, what it does and why.

I could have used Claude Code. At the cost of a great many more (pricey) tokens, it’d have mapped the entire code base of my WISPL chatbot. It’d have implemented its changes without a human in the loop. It’d have committed those changes to my git repository, and pushed them to GitHub. It would, quite likely, have also presented a nice explanation of what it did and why, which I could read at my convenience… or not. Because, well, if the solution works, what’s the point?

And that is how we gradually lose agency over our projects when we allow AI systems to act not just as assistants but also as agents.

Yes, I tried. I have a working Claude Code installation. My reaction was negative due to the opacity of the process. Claude goes away, does things… maybe asks for permission to modify the code base, maybe not, depending on the setting… and then comes back when it is done. Chances are the result works, or at least, appears to work. How could I even tell the difference?

And I’ve seen the consequences of this already. There were publicly disclosed cases but I also interacted with folks who let Claude Code go a tad too far.

As for me, I’d prefer to continue using AI systems as assistants. An AI assistant is like an incredibly capable, knowledgeable, tireless junior programmer: I retain the senior programmer role. The junior programmer may be writing the code, but I am the one reviewing it, integrating it, validating it. With a coding agent, the situation changes. The coding agent is not just a junior programmer: it’s an entire development team. My role? That of the detached project manager who know things in PowerPoint slides and KPIs, and no longer has an in-depth understanding, intellectual “ownership” of the code proper.

This is especially dangerous when the project involves unfamiliar code. The coding agent can review, map, “understand” that code base and make changes to it, while I remain in the dark. The AI may offer explanations, but it’s not quite the same as hands-on experience with the code base. I may not be aware of the broader context, and accept the (plausible) explanations at face value.

In any case, the agentic productivity gain is not quite as great as this DALL-E illustration might imply. As my search engine replacement surgery demonstrates, the bulk of the productivity gain comes from writing good quality code fast. The perceived gain with the agent comes at a huge cost: a bird’s eye view of the project is not the same as robust understanding of its architecture and details.

Indeed, paradoxically, the ones who benefit the most from the extra productivity gain offered by coding agents are the ones who should be most wary of it: people with less experience than I have. The biggest productivity gain from agentic behavior is for users who are least equipped to supervise the agent safely. And that, I worry, will lead to many more software development horror stories in the coming years.

 Posted by at 11:00 pm
Apr 252026
 

Although I tried it, I am not using Claude Code or any of the other “agentic” coding tools provided by AI companies. However, I do use their models as coding assistants. What I don’t need is an “agent” that compiles code, manages git repos, or, well, messes up my system. What I do need is an efficient, extremely knowledgeable coding assistant who can complete in minutes what would take hours, days, perhaps even weeks for me to write.

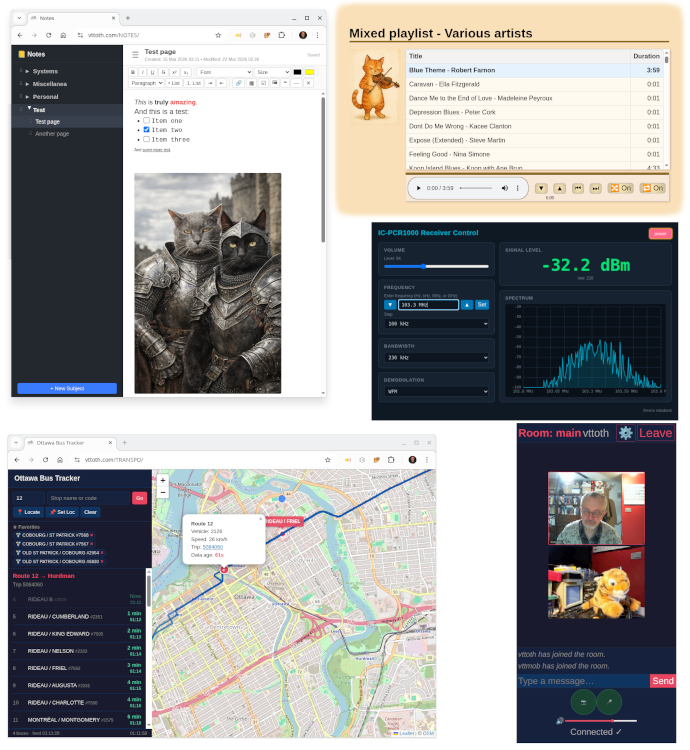
Take a look at this selection of Web apps I recently created, for my own use, really.

In the upper left, a note-taker app that I have now been using for over a month as my “on premises” replacement of Microsoft OneNote. Works like a charm, better than OneNote in a variety of ways.

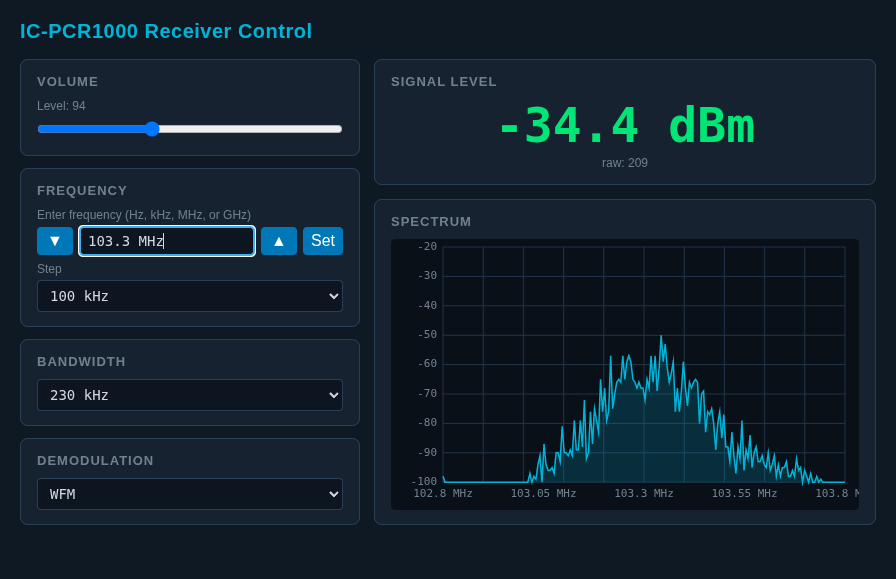
Going clockwise, the next app is my custom music player. It’s integrated with my private library of my ripped CDs. Next is an app that controls my IC-PCR1000 radio. This radio is just a little black box, connected to a PC via a serial cable. (Yes, it’s that old.) It’s an “almost professional grade” communications receiver that basically covers the continuous radio spectrum from 10 kHz to 1.3 GHz. I am not doing anything fancy with it these days, just listening (mostly) to CBC Radio 2 or Radio Canada’s Ici Musique.

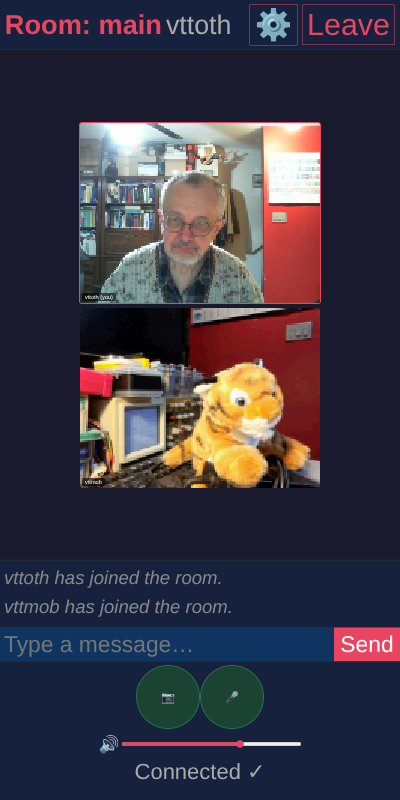
Then there is is a group video chat app that I specifically developed to overcome issues with video not properly transmitted behind firewalls or over VPNs. It’s TCP-only, which of course has its disadvantages, but it works reasonably well. Shown here is the mobile version of its user interface: a plush tiger happily volunteered to be my chat partner in a test.

Finally, a bus tracker app, using real-time data from Ottawa’s public transportation company, OC Transpo. As the data format they use is a Google standard that is now used by many other municipalities, I am thinking of adapting my app to work, e.g., using data from Budapest. For now, it just does what it was supposed to do in the first place, covering Ottawa, with real-time refresh and updates.

For me, this represents the true power of LLMs in software development. None of that agentic nonsense. I don’t need the AI to do typing for me. I need the AI to spit out 1000 lines of mostly correct code in a matter of seconds, saving me countless hours of development time. What it enables is for me to create bespoke software that does exactly what I need it to do. But in the end, I “own” the code, I understand what it does, how it works, I can debug and refine it without AI help if necessary. The agency remains mine.

 Posted by at 1:54 am
Mar 282026
 

Very well, I was not really chatting or conferencing with a toy animal. My wife’s little tiger just served as a prop, since he was far more likely to stay put than any of our actual miniature tigers, I mean cats.

In any case, the point was not so much who I was chatting with but how: I was doing so using my very own little conferencing service, implemented in half an afternoon with prodigious coding help from Claude.

No, not “vibe coding”. I tried “vibe coding” and it’s not my cup of tea. Not because I am a control freak but because I like to know what my applications do and why, and how to fix and debug them. Moreover, I don’t mind owning the concept. That’s not the time-consuming part. The time-consuming part is implementation and this is where coding assistants, Claude in particular, excel. Don’t outsource combinatorial reasoning, like navigating the excessive landscape of design options. Nor do I need a coding agent type commands for me (and, on a bad day, wipe out my code base.) What I need the AI for is to write the routine stuff once the design is settled.

That is exactly what we did here, and the result… well, works. The concept is simple: Keep everything TCP. Of course TCP is the worst choice for real-time media streaming, except for the alternative: UDP works until it doesn’t, because it is blocked by a NAT-firewall, a mobile network policy, or something else. In fact, it was my struggle to get things run well in these post-Skype days that led me to my simple (but not simplistic) implementation: sending compressed, differenced video and audio at a bandwidth that remains manageable even with my self-hosted relay host for up to maybe half a dozen users.

The thing works. Granted, so far I only tested it with two users (me and me) but it works robustly and reliably even over a cellular connection. I might soon get a chance to test it with real users, some friends. Until then, I have my plush tiger to talk to.

All in all, 2000+ lines of good quality, working code in half an afternoon. That’s what a good AI assistant can do under competent supervision.

 Posted by at 1:09 am
Mar 132026
 

I have an old radio: an ICOM IC-PCR1000. It’s a nondescript little black box, with no controls other than a power switch. It is controlled by a computer.

Its age is perfectly characterized by this simple fact: It is controlled through a serial port, good old RS-232. Not even USB.

It works perfectly well. Or rather, it did, under Windows, with its 25-year old control software. But that same software cannot reliable connect to the radio under Linux, via Wine. It runs, it connects, but every few seconds it reports an error despite the fact that it seems to read and control the radio just fine.

Well, I solved the problem now, with the help of Claude. No, not “vibe” programming: the concept is mine, in fact it is based on software I myself wrote some 12 years ago. At that time, I was experimenting with a C-sharp back end connecting to the radio. This time around? A plain C back-end (a translation done by ChatGPT) and a front-end and midware in HTML+JS and PHP.

So the code logic is mine, even as Claude saved me a lot of time. The layout and visual appearance, however, are entirely Claude’s doing, Claude 4.6 Opus in particular, running on my WISPL Web site. I only introduced some very minor tweaks to refine the appearance.

And yes, I am using it right now, listening to CBC Radio 2.

 Posted by at 9:42 pm
Nov 282025
 

Behind every front-end there is a back-end. My WISPL.COM chatbot is no exception. It’s one thing to provide a nice chatbot experience to my select users. It’s another thing to be able to manage the system efficiently.

Sure, I can, and do, management tasks directly in the database, using SQL commands. But it’s inelegant and inconvenient. And just because I am the only admin does not mean I cannot make my own life easier by creating a more streamlined management experience.

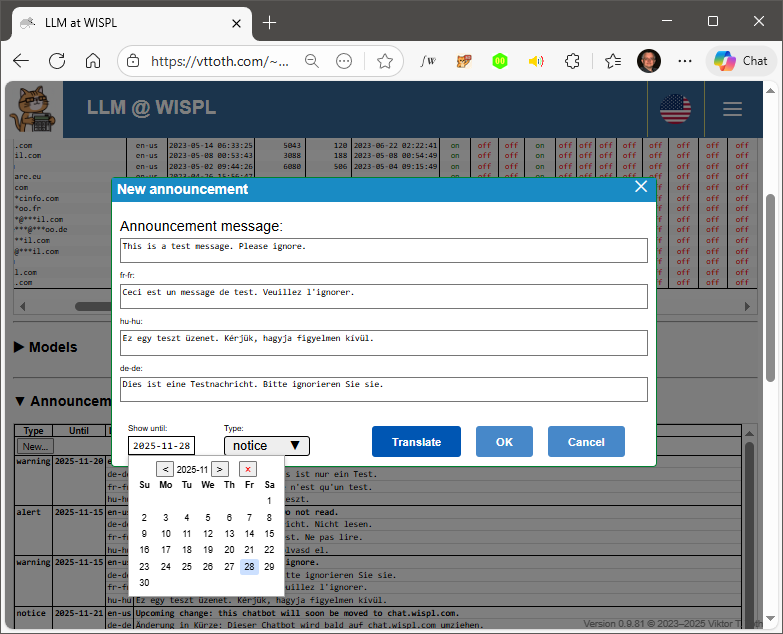
Take announcements. The WISPL chatbot operates in four languages. Creating an announcement entails writing it in a primary language, translating it into three other languages, and the posting the requisite records to the database. Doing it by hand is not hard, but a chore.

Well, not anymore. I just created a nice back-end UI for this purpose. By itself it’s no big deal of course, but it’s the first time the software itself uses a large language model for a targeted purpose.

Note the highlighted Translate button. It sends the English-language text to a local copy of Gemma, Google’s open-weights LLM. Gemma is small but very capable. Among other things, it can produce near flawless translations into, never mind German or French, even Hungarian.

This back-end also lets me manage WISPL chatbot users as well as the language models themselves. It shows system logs, too.

 Posted by at 5:44 pm
Nov 092025
 

A few weeks ago I had an idea.

What if I implement a GPT? No, not something on the scale of ChatGPT, with many hundreds of billions of parameters, consuming countless terawatt-hours, training on a corpus that encompasses much of the world’s literature and most of the Internet.

No, something far more modest. How about… a GPT that emulates the world’s first chatbot, Eliza?

Long story short (the long story will follow in due course on my Web site) I succeeded. I have built a GPT from scratch in C++, including training. I constructed a sensible (though far from perfect) training corpus of user prompts and Eliza responses. And over the course of roughly a week, using a consumer-grade GPU for hardware acceleration, I managed to train my smallest model.

No, don’t expect perfection. My little model does not have hundreds of billions of parameters. It does not even have millions of parameters. It is only a 38 thousand (!) parameter model.

Yet… it works. Sometimes its output is gibberish. But most of the time, the output is definitely Eliza-like.

The best part? The model is so small, its inference runtime works well when implemented in JavaScript, running in-browser.

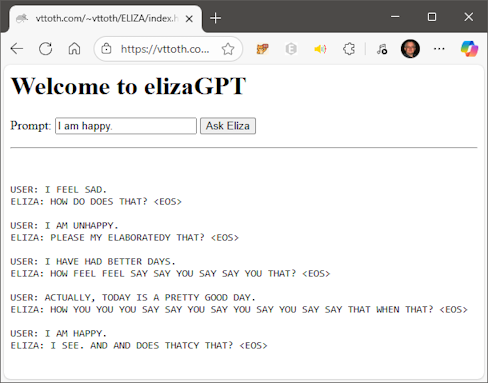
And here is my first ever exchange with the JavaScript implementation, unfiltered and unedited.

No, I am not going to win awards with this chatbot, but the fact that it works at all, and that it successfully learned the basic Eliza-like behavior is no small potatoes.

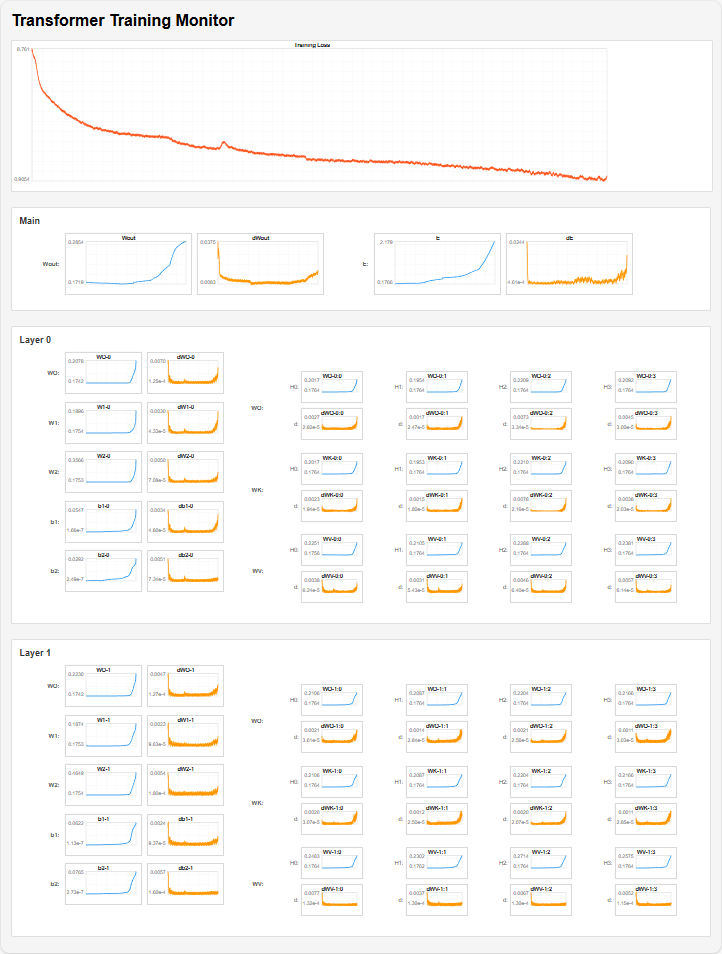
For what it’s worth, I was monitoring its training using a little bit of homebrew near-real-time instrumentation, which allowed me to keep an eye on key model parameters, making sure that I intervene, adjusting learning rates, to prevent the training from destabilizing the model.

I am now training a roughly 10 times larger version. I do not yet know if that training will be successful. If it is, I expect its behavior will be more robust, with less gibberish and more Eliza-like behavior.

In the meantime, I can now rightfully claim that I know what I am talking about… after all, I have a C++ implementation, demonstrably working, complete with backpropagation, by way of credentials.

 Posted by at 1:40 am
Sep 302025
 

There is a wonderful tool out there that works with many of the published large language models and multimodal models: Llama.cpp, a pure C++ implementation of the inference engine to run models like Meta’s Llama or Google’s Gemma.

The C++ implementation is powerful. It allows a 12-billion parameter model to run at speed even without GPU acceleration, and emit 3-4 tokens per second in the generation phase. That is seriously impressive.

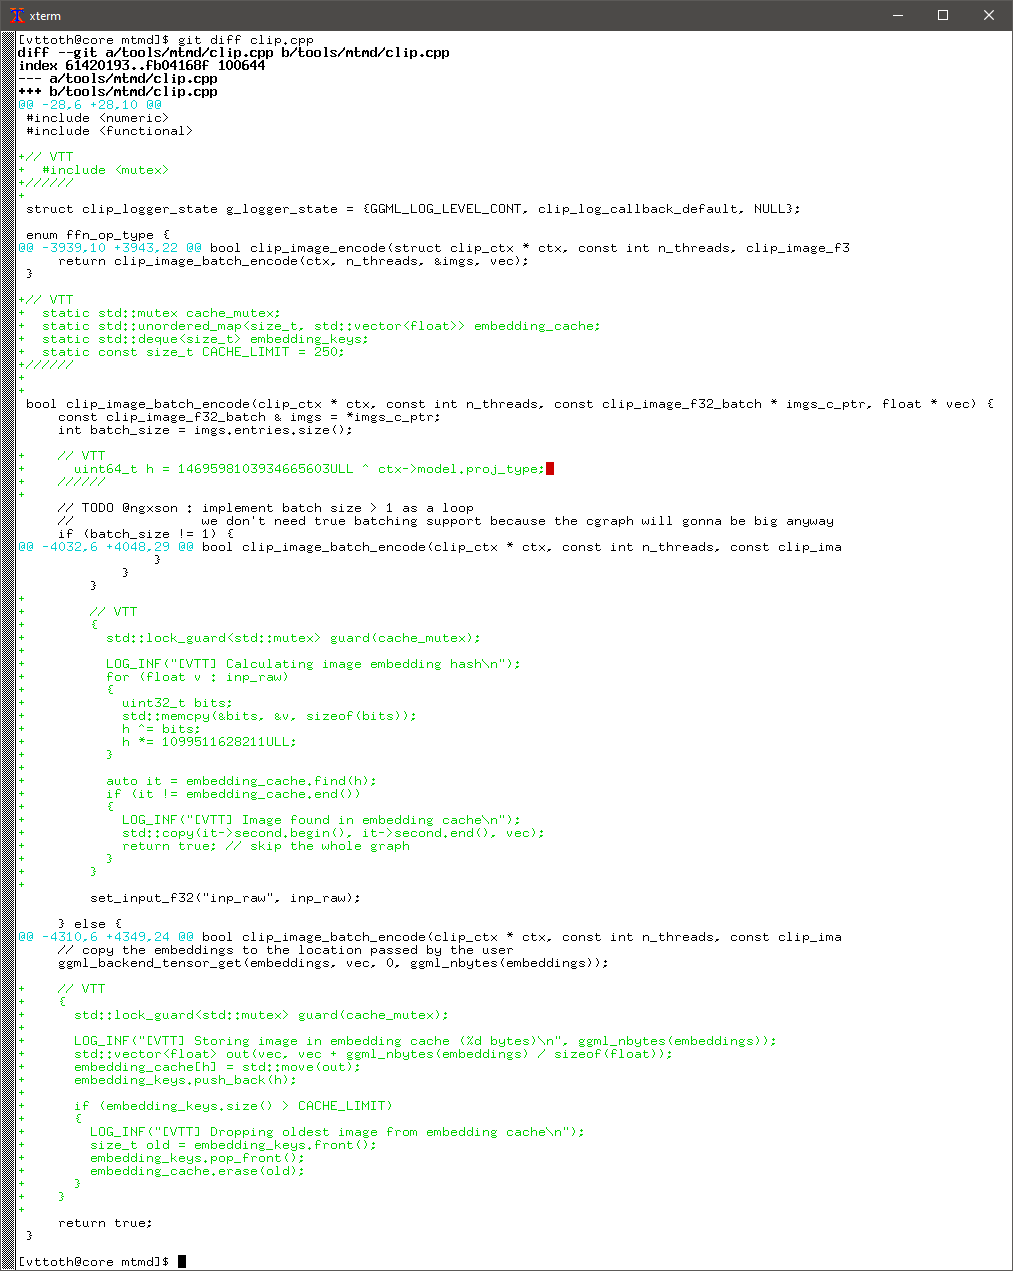
There is one catch. Multimodal operation with images requires embedding, which is often the most time-consuming part. A single image may take 45-60 seconds to encode. And in a multi-turn conversation, the image(s) are repeatedly encoded, slowing down the conversation at every turn.

An obvious solution is to preserve the embeddings in a cache and avoid re-embedding images already cached. Well, this looked like a perfect opportunity to deep-dive into the Llama.cpp code base and make a surgical change. A perfect opportunity also to practice my (supposedly considerable) C++ skills, which I use less and less these days.

Well, what can I say? I did it and it works.

I can now converse with Gemma, even with image content, and it feels much snappier.

 Posted by at 2:21 am
Sep 172025
 

Yet another thing I just had to do: upgrading my server to PHP 8, because increasingly, PHP 7 (though still legacy supported by Oracle OS 8) was no longer compatible with upcoming versions of content management code that I use.

So far so good… expect glitches, of course.

Much as I appreciate the effort and value we all receive from open source projects, I think I shall just keep it to myself what I think of forced upgrades and broken backwards compatibility for reasons of code purity.

 Posted by at 12:42 am
Jul 292025
 

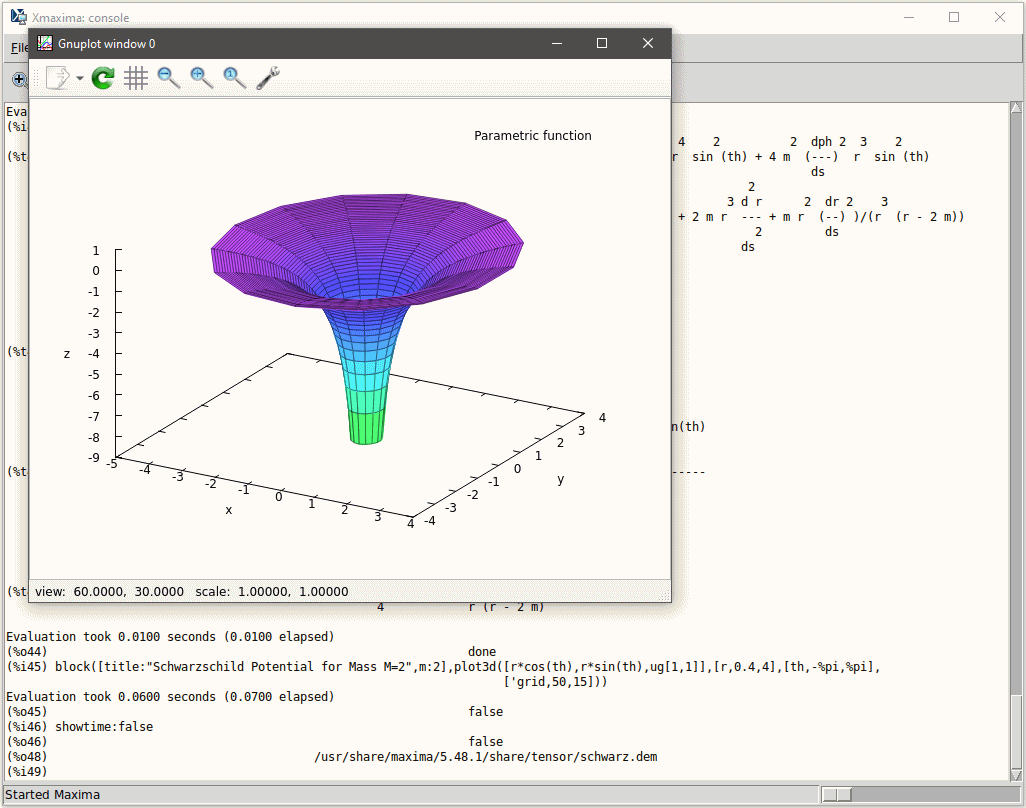
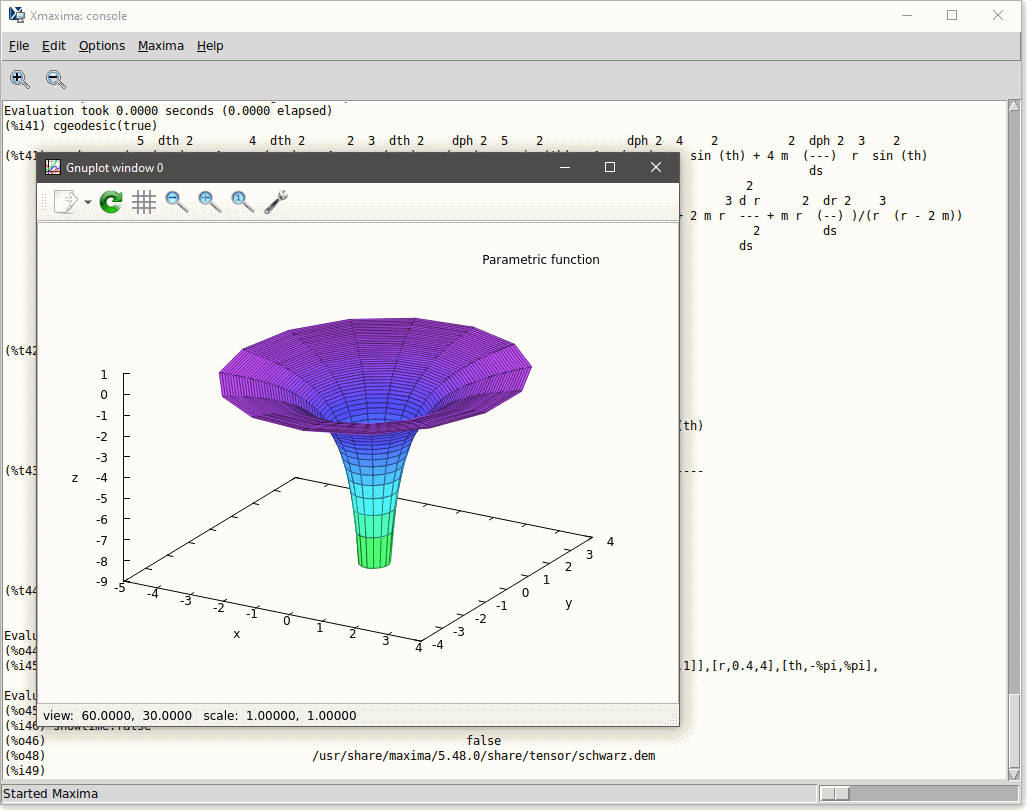
I just completed the process to release Maxima 5.48.

The new version introduces several noteworthy enhancements for symbolic computation, with improvements in performance, functionality, and user experience.

Highlights:

– Unicode-enabled output (when supported by the Lisp compiler)
– Numerous performance improvements across core routines
– New package for symbolic radical denesting
– New package for inferring closed-form expressions from sequences
– New package for simplification of gamma functions
– Resolution of more than 150 tickets, spanning both long-standing and recent bugs

Developed in Common Lisp, Maxima remains a reliable and customizable tool for research, education, science, and engineering.

To install, explore, or contribute: https://maxima.sourceforge.io

 Posted by at 2:56 am
Jul 272025
 

I have added some new apps to my Web site. One, a bit serious, the other, less so.

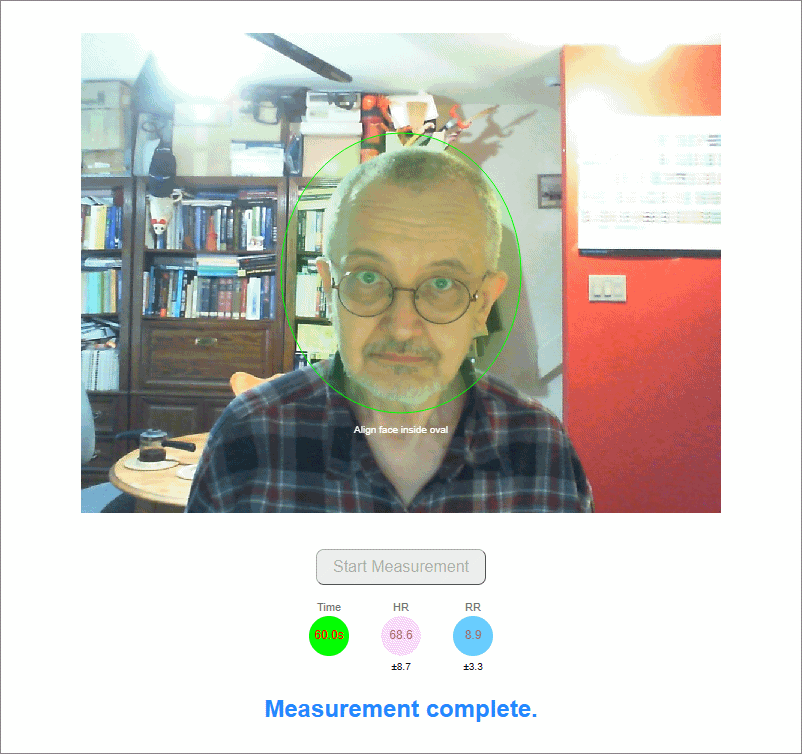
The serious one: a technology demonstration, showing that it is not black magic to use a Web camera and try to extract from its feed an estimate of a person’s heart rate and (less reliably) respiratory rate. The measurement is not perfect, of course, but it works surprisingly well at least some of the time.

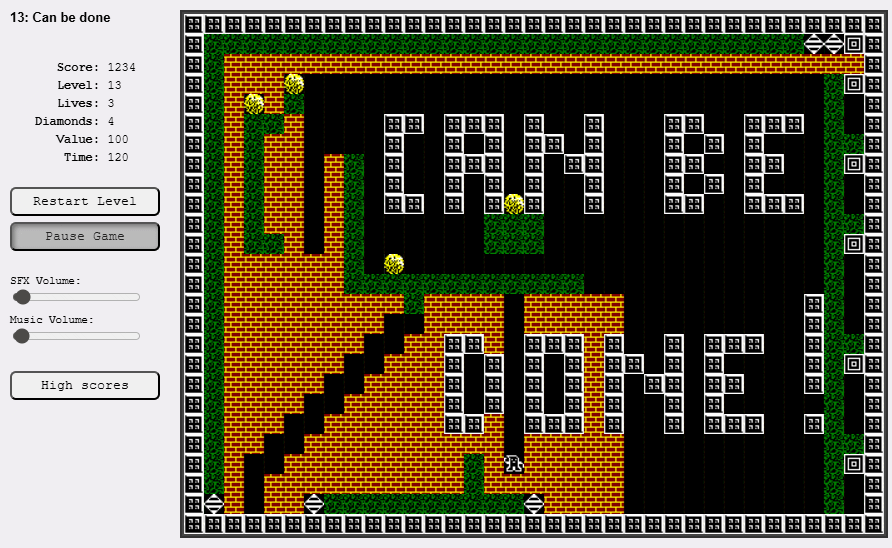
Meanwhile, I also resurrected an old project of mine, one I initially did in 1993: itself a resurrection of an even older game from back in the heroic 8-bit days. I was inspired by a DOS version on Usenet, itself derived from an earlier X11 version; it became my first “full-featured” Visual C++ project, originally developed for Windows 3.1. A 32-bit version followed two years later, and that was the basis of my current, Web-based reimplementation. I called my version Rubble Rush, to avoid infringing on the original’s (still extant, as far as I know) trademark.

These implementations also showcase how easy it is, using modern JavaScript, to develop solutions with real-time interactivity, also using real-time media streams to boot.

 Posted by at 5:08 pm
May 132025
 

A friend of mine challenged me. After telling him how I was able to implement some decent neural network solutions with the help of LLMs, he asked: Could the LLM write a neural network example in Commodore 64 BASIC?

You betcha.

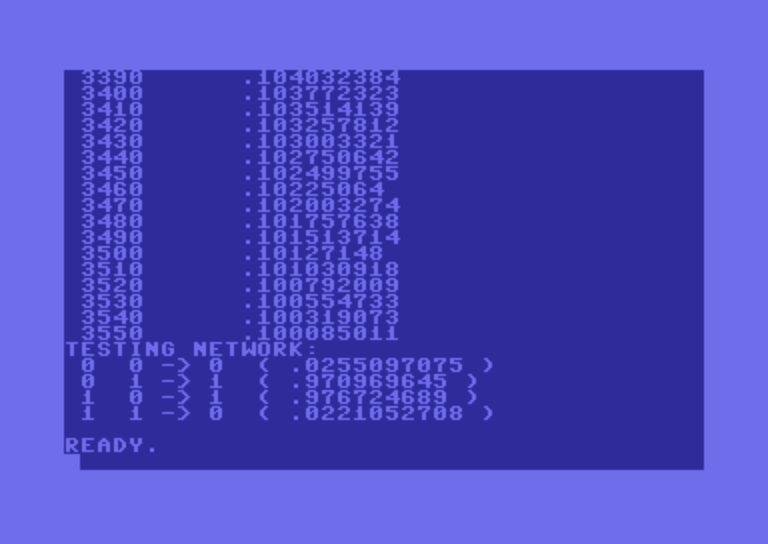
Well, it took a few attempts — there were some syntax issues and some oversimplifications so eventually I had the idea of asking the LLM to just write the example on Python first and then use that as a reference implementation for the C64 version. That went well. Here’s the result:

As this screen shot shows, the program was able to learn the behavior of an XOR gate, the simplest problem that requires a hidden layer of perceptrons, and as such, a precursor to modern “deep learning” solutions.

I was able to run this test on Krisztián Tóth’s (no relation) excellent C64 emulator, which has the distinguishing feature of reliable copy-paste, making it possible to enter long BASIC programs without having to retype them or somehow transfer them to a VIC-1541 floppy image first.

In any case, this is the program that resulted from my little collaboration with the Claude 3.7-sonnet language model:

10 REM NEURAL NETWORK FOR XOR PROBLEM
20 REM BASED ON WORKING PYTHON IMPLEMENTATION

100 REM INITIALIZE VARIABLES
110 DIM X(3,1) : REM INPUT PATTERNS
120 DIM Y(3) : REM EXPECTED OUTPUTS
130 DIM W1(1,1) : REM WEIGHTS: INPUT TO HIDDEN
140 DIM B1(1) : REM BIAS: HIDDEN LAYER
150 DIM W2(1) : REM WEIGHTS: HIDDEN TO OUTPUT
160 DIM H(1) : REM HIDDEN LAYER OUTPUTS
170 DIM D1(1,1) : REM PREVIOUS DELTA FOR W1
180 DIM B2 : REM BIAS: OUTPUT LAYER
190 DIM D2(1) : REM PREVIOUS DELTA FOR W2
200 DIM DB1(1) : REM PREVIOUS DELTA FOR B1
210 DB2 = 0 : REM PREVIOUS DELTA FOR B2
220 LR = 0.5 : REM LEARNING RATE
230 M = 0.9 : REM MOMENTUM

300 REM SETUP TRAINING DATA (XOR PROBLEM)
310 X(0,0)=0 : X(0,1)=0 : Y(0)=0
320 X(1,0)=0 : X(1,1)=1 : Y(1)=1
330 X(2,0)=1 : X(2,1)=0 : Y(2)=1
340 X(3,0)=1 : X(3,1)=1 : Y(3)=0

400 REM INITIALIZE WEIGHTS RANDOMLY
410 FOR I=0 TO 1
420 FOR J=0 TO 1
430 W1(I,J) = RND(1)-0.5
440 NEXT J
450 B1(I) = RND(1)-0.5
460 W2(I) = RND(1)-0.5
470 NEXT I
480 B2 = RND(1)-0.5


510 REM INITIALIZE MOMENTUM TERMS TO ZERO
520 FOR I=0 TO 1
530 FOR J=0 TO 1
540 D1(I,J) = 0
550 NEXT J
560 D2(I) = 0
570 DB1(I) = 0
580 NEXT I
590 DB2 = 0

600 REM TRAINING LOOP
610 PRINT "TRAINING NEURAL NETWORK..."
620 PRINT "EP","ER"
630 FOR E = 1 TO 5000
640 ER = 0
650 FOR P = 0 TO 3
660 GOSUB 1000 : REM FORWARD PASS
670 GOSUB 2000 : REM BACKWARD PASS
680 ER = ER + ABS(O-Y(P))
690 NEXT P
700 IF (E/10) = INT(E/10) THEN PRINT E,ER
710 IF ER < 0.1 THEN E = 5000
720 NEXT E

800 REM TEST NETWORK
810 PRINT "TESTING NETWORK:"
820 FOR P = 0 TO 3
830 GOSUB 1000 : REM FORWARD PASS
840 PRINT X(P,0);X(P,1);"->"; INT(O+0.5);" (";O;")"
850 NEXT P
860 END

1000 REM FORWARD PASS SUBROUTINE
1010 REM CALCULATE HIDDEN LAYER
1020 FOR I = 0 TO 1
1030 S = 0
1040 FOR J = 0 TO 1
1050 S = S + X(P,J) * W1(J,I)
1060 NEXT J
1070 S = S + B1(I)
1080 H(I) = 1/(1+EXP(-S))
1090 NEXT I
1100 REM CALCULATE OUTPUT
1110 S = 0
1120 FOR I = 0 TO 1
1130 S = S + H(I) * W2(I)
1140 NEXT I
1150 S = S + B2
1160 O = 1/(1+EXP(-S))
1170 RETURN

2000 REM BACKWARD PASS SUBROUTINE
2010 REM OUTPUT LAYER ERROR
2020 DO = (Y(P)-O) * O * (1-O)
2030 REM UPDATE OUTPUT WEIGHTS WITH MOMENTUM
2040 FOR I = 0 TO 1
2050 DW = LR * DO * H(I)
2060 W2(I) = W2(I) + DW + M * D2(I)
2070 D2(I) = DW
2080 NEXT I
2090 DW = LR * DO
2100 B2 = B2 + DW + M * DB2
2110 DB2 = DW
2120 REM HIDDEN LAYER ERROR AND WEIGHT UPDATE
2130 FOR I = 0 TO 1
2140 DH = H(I) * (1-H(I)) * DO * W2(I)
2150 FOR J = 0 TO 1
2160 DW = LR * DH * X(P,J)
2170 W1(J,I) = W1(J,I) + DW + M * D1(J,I)
2180 D1(J,I) = DW
2190 NEXT J
2200 DW = LR * DH
2210 B1(I) = B1(I) + DW + M * DB1(I)
2220 DB1(I) = DW
2230 NEXT I
2240 RETURN

The one proverbial fly in the ointment is that it took about two hours for the network to be trained. The Python implementation? It runs to completion in about a second.

 Posted by at 12:45 am
Jan 102024
 

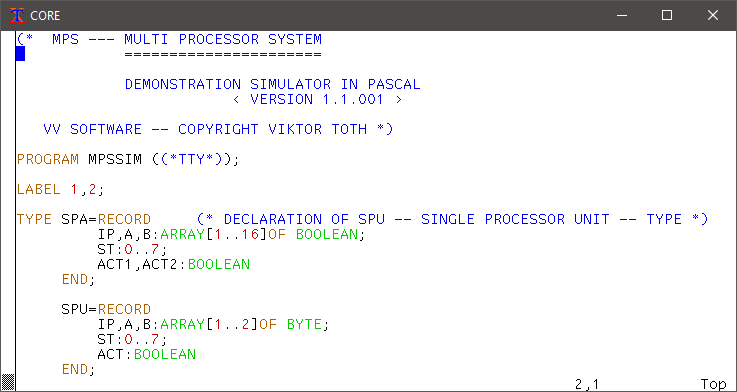
Here are the first few lines of a program I wrote over 40 years ago, an early attempt to model a massively parallel processor architecture.

No, the program is nothing special. And there are much better ways to create practical multiprocessor/multicore systems. The reason why I copy-pasted this image here has to do with something else: the fact that it was written in the Pascal programming language.

Pascal was just one of the many creations of one of the giants of computer science, Niklaus Wirth.

I learned yesterday that Wirth, who was born back in 1934, passed away on January 1.

 Posted by at 10:31 pm
Dec 142023
 

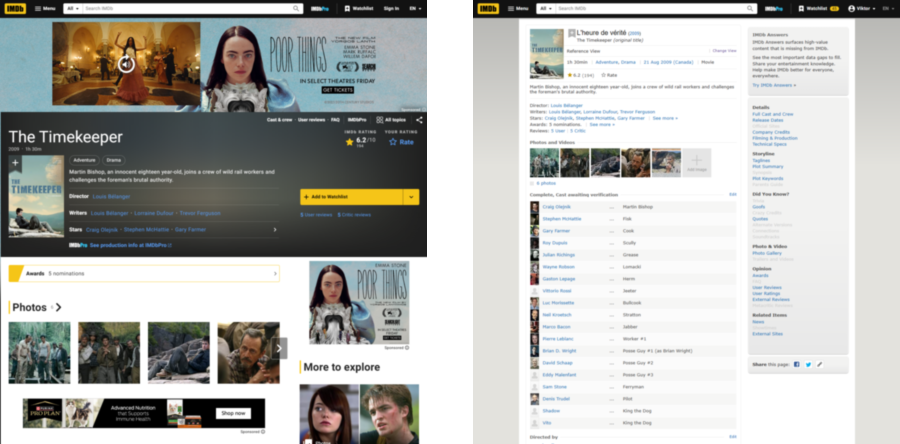
I wanted to check something on IMDB. I looked up the film. I was confronted by an unfamiliar user interface. Now unfamiliar is okay, but the UI I saw is badly organized, key information (e.g., year of release, country of origin) difficult to find, with oversized images at the expense of useful content. And no, I don’t mean the ads; I am comfortable with relevant, respectful ads. It’s the fact that a lot less information is presented, taking up a lot more space.

Fortunately, in the case of IMDB I was able to restore a much more useful design by logging in to my IMDB account, going to account settings, and making sure that the Contributors checkbox was checked. Phew. So much more (SO MUCH MORE) readable, digestible at a glance. Yes, it’s smaller print. Of course. But the information is much better organized, the appearance is more consistent (no widely different font sizes) and the page is dominated by information, not entertainment in the form of images.

IMDB is not the only example. Recently, after I gave it a valiant try, I purposefully downgraded my favorite Android e-mail software as its new user interface was such a letdown. At least I had the foresight to save the APK of the old version, so I was able to install it and then make sure in the Play Store settings that it would not be upgraded. Not that I am comfortable not upgrading software but in this case, it was worth the risk.

All this reminds me of a recent discussion with a friend who works as a software professional himself: he is fed up to his eyeballs with the pervasive “Agile” fad at his workplace, with its mandatory “Scrum” meetings and whatnot. Oh, the blessings of being an independent developer: I could tell him that if a client mentioned “Agile” more than once, it’d be time for me to “Scrum” the hell out of there…

OK, I hope it’s not just grumpy ole’ complaining on my part. But seriously, these trendy fads are not helping. Software becomes less useful. Project management culture reinvents the wheel (I have an almost 50-year old Hungarian-language book on my shelf on project management that discusses iterative management in depth) with buzzwords that no doubt bring shady consultants a lot more money than I ever made actually building things. (Not complaining. I purposefully abandoned that direction in my life 30 years ago when I quietly walked out of a meeting, not having the stomach anymore to wear a $1000 suit and nod wisely while listening to eloquent BS.) The result is all too often a badly managed project, with a management culture that is no less rigid than the old culture (no fads can overcome management incompetence) but with less documentation, less control, less consistent system behavior, more undocumented dependencies, and compromised security. UI design has fads that change with the seasons, united only by results that are about as practical as a Paris fashion designer’s latest collection of “work attire”.

OK, I would be lying if I said that only bad things come out of change. Now that I use AI in software development, not a day goes by without the AI teaching me something I did not know, including tools, language features and whatnot that can help improve the user experience. But it would be so nice if we didn’t take three steps back for every four steps forward.

 Posted by at 10:21 am
Nov 302023
 

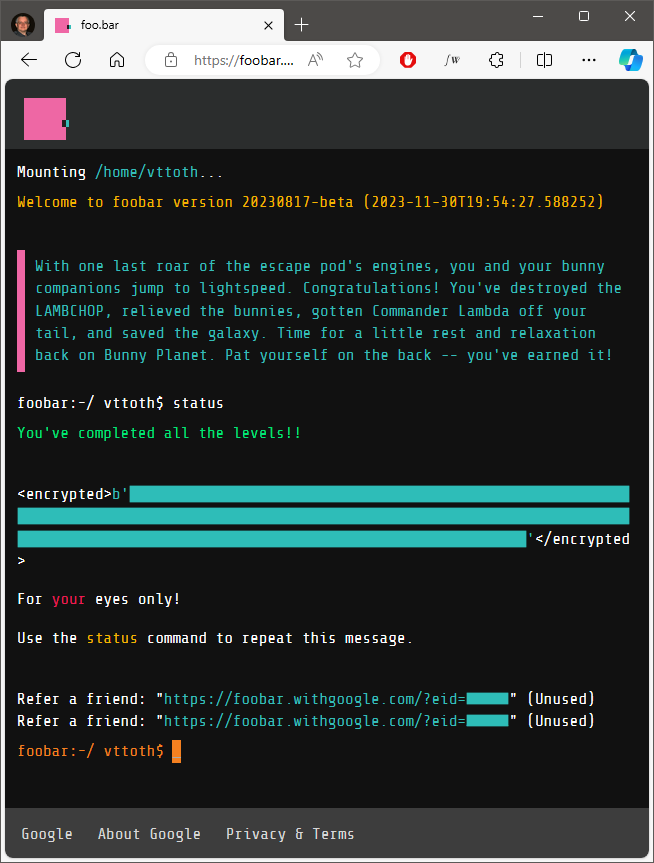
So the other day, as I was doing a Google Search (can’t exactly remember what it was that I was searching for but it was machine learning related), up pops this invitation to participate in a challenge.

Turned out to be the Google Foobar challenge, Google’s secret recruiting tool. (Its existence is not really a secret, so I am not really revealing any great secrets here.)

Though I have no plans to become a Google employee (and I doubt they’re interested in me on account of my age anyway) I decided to go through the challenge because, well, it’s hard to say no to a challenge, and it was an opportunity to practice my Python skills (which need a lot of practice, because I have not yet used Python that much.)

Well, I did it. It was fun.

More importantly, I enjoyed it just as much as I enjoyed similar challenges as a math geek in my early teens. And if that’s not a gift from life, I don’t know what it is.

And yes, I am now much better at Python than I was just a few days ago. I certainly appreciate why the language has become popular, though I can also see its non-trivial pitfalls.

 Posted by at 6:03 pm
Aug 122023
 

One of the many unfulfilled, dare I say unfulfillable promises of the tech world (or at least, some of the tech world’s promoters) is “low code”. The idea that with the advent of AI and visual programming tools, anyone can write code.

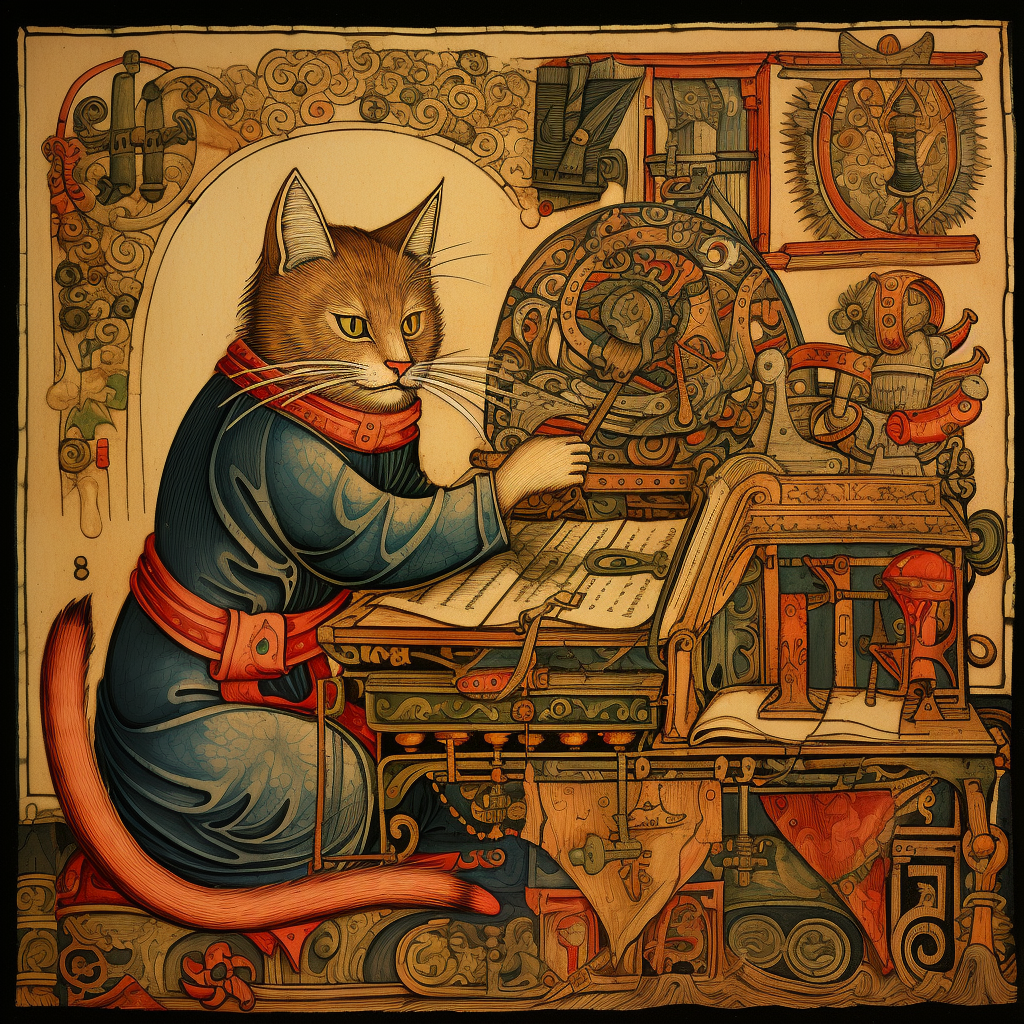
Recall how medieval scribes prepared those beautiful codices, illuminated manuscripts. Eventually, that profession vanished, replaced by the printing press and, eventually, the typewriter. But what if someone suggested that with the advent of the typewriter, anyone can now write high literature? Laughable, isn’t it. There is so much more to writing than the act of making nicely formed letters appear on a sheet of paper.

Software development is just like that. It is about so much more than the syntax of a programming language. Just think of the complete life cycle of a software development project. Even small, informal in-house projects follow this model: A requirement is identified, a conceptual solution is formulated (dare I say, designed), the technology is selected, problems are worked out either in advance or as they are encountered during testing. The code is implemented and tested, bugs are fixed, functionality is evaluated. The code, if it works, is put into production, but it still needs to be supported, bugs need to be fixed, compatibility with other systems (including the operating system on which it runs) must be maintained, if it is a public-facing app, its security must be monitored, business continuity must be maintained even if the software fails or there are unexpected downtimes… These are all important aspects of software development, and they have very little to do with the act of coding.

In recent months, I benefited a great deal from AI. Claude and, especially perhaps, GPT-4, proved to be tremendous productivity tools of almost unbelievable efficiency. Instead of spending hours on Google searches or wading through StackExchange posts, I could just consult Claude and get an instant answer clarifying, e.g., the calling conventions of a system function. When I was struggling to come up with a sensible way to solve a problem, I could just ask GPT-4 for suggestions. Not only did GPT-4 tell me how to address the problem at hand, often with helpful code snippets illustrating the answer, it even had the audacity to tell me when my approach was suboptimal and recommended a better solution.

And yes, I could ask these little robot friends of ours to write code for me, which they did.

But this was when things took a really surprising turn. On several occasions, Claude or GPT not only offered solutions but offered inspired solutions. Elegant solutions. Except that the code they wrote had bugs. Sometimes trivial bugs like failure to initialize a variable or assigning a variable that was declared a constant. The kind of routine mistakes experienced programmers make, which are easily fixable: As the first, draft version of the code is run through the compiler or interpreter, these simple buglets are readily identified and corrected.

But this is the exact opposite of the “low code” promise. Low code was supposed to mean a world in which anyone can write software using AI-assisted visual tools. In reality, those tools do replace armies of inexperienced, entry-level programmers but experience is still required to design systems, break them down into sensible functional components, create specifications (even if it is in the form of a well-crafted prompt sent to GPT-4), evaluate solutions, perform integration and testing, and last but not least, fix the bugs.

What worries me is the fact that tomorrow’s experienced software architects will have to come from the pool of today’s inexperienced entry-level programmers. If we eliminate the market for entry-level programmers, who will serve as software architects 20, 30 years down the line?

Never mind. By then, chances are, AI will be doing it all. Where that leaves us humans, I don’t know, but we’re definitely witnessing the birth of a brand new era, and not just in software development.

 Posted by at 12:23 pm