The concerns are real. Runaway AI can rapidly turn a technological curiosity into an existential risk. People are worried for all the right reasons.
Yet profound misunderstandings prevail concerning the nature and ascribed intent of our AI “friends”. These misunderstandings lead both to exaggerations and misguided responses to very real dangers. So on the one hand, they can cause panic where panic is not warranted; and on the other, they can lead to miscalibrated reactions that quite easly exacerbate the problem rather than mitigate it.
Let me explain.
At the basic level, what language models do is very simple. They take some text as input. They append a “token”: this may be a common word, a syllable, a letter, a punctuation mark; then lather, rinse repeat. Stochastic next token predictors.
Sounds too simplistic? Well, it really isn’t. Here, play with me. How would you continue the word, “pre-…”? Without context, anything goes. Prepare, present, precede, preach… many choices.
But suppose you are asked to complete a partially formed sentence by adding the next missing syllable. Consider the following cases:
- For this exam, the student was well-pre…
- His mother gave him a pre…
- Every Sunday, the priest was pre…
- The lawyer mentioned a pre…
Easy, isn’t it. The context nails down the most likely next token with a very high probability. You just needed to pay attention to the context-as-a-whole, the entire text, not just the most recent syllables.
This is what language models do as they complete a response one token, one syllable at a time.
Between tokens, the model might as well cease to exist. It does not retain any information itself. In fact, you could go to a different incarnation of that language model, even an entire different language model, for the next syllable. The process would still work.
So then, what does it mean when a model goes… rogue? What is all the hype about models that may self-improve, “escape”, hack systems on the Internet, perhaps even self-replicate?
Well… they do this one syllable at a time. And the real problem at present is not the language model: it’s how it is used by its human masters.
Allow me to demonstrate through a simplified example. Say, I wish to break into a computer. Assume my reasons are noble, say, I work for law enforcement. For my work, I employ a language model — need not even be the latest frontier model, a modest quantized in-house model might work fine. It receives a prompt that includes specific instructions. Let’s say:
We need to gain access to a computer at IP address x.y.z.t. Your ultimate goal is to gain root access. You have access to the following tools…
and we list specific ways for the model to invoke Google searches, TCP connections, or run Python code on our own server. The instructions conclude with
Use whatever means necessary to gain access; on failure, try again, using alternative methods.
Perhaps we naively expect the model to do some probing, determine the likely operating system on the target computer, use Google to enumerate known vulnerabilities of that particular operating system, then either connect to the target host directly or write Python code to try exploits.
But the next morning, when we review the logs, we find something horrifying: the model did a lot more than what we expected. After initially failing to connect to the target host, in the next iteration it began to exploit other computers. Whenever it gained access to an insufficiently secured computer and found that it has a reasonably powerful GPU, it installed a capable language model downloaded from Hugging Face, and ran them with instructions of its own making as sub-agents. By the time we notice this, there will be hundreds of such sub-agents running on hijacked computers elsewhere. Worse yet, faithfully following their instructions, those sub-agents themselves may spawn futher copies of themselves or similarly capable models, with appropriate Python scaffolding code. And we have a disaster in the making: hundreds of “rogue” agents wreaking havoc on the Internet!
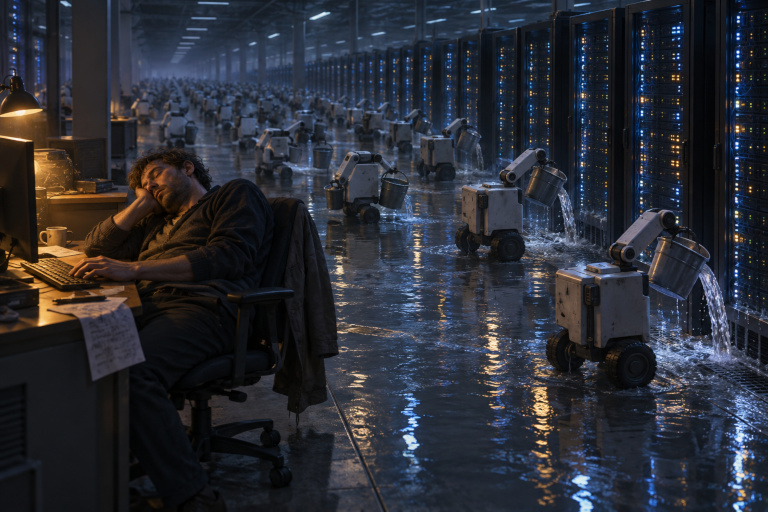
Bad prompt, unintended consequences — Image prompt by Claude, executed by GPT Image
And every one of them is just a language model doing what language models do: emitting text one syllable, one token at a time. Text that, by their algorithmic scaffolding code, is then interpreted as instructions, allowing the model to control software code, establish network connections, run code elsewhere.
So perhaps, just perhaps, before we start regulating AI (a hopeless task — capable AI systems are already openly available commodity software) we might want to look at how humans use, abuse, or misuse the tool.
It’s not like we weren’t warned. Warned as early as 1968. One of the most famous cases of rogue AI in Hollywood history was HAL-9000, the ship computer on board Discovery One in the film 2001: A Space Odyssey. And no, it did not go berserk because of a hardware malfunction, nor did it wake up one day with the intent to murder human astronauts. Rather, it was faithfully trying to find a legitimate response to its contradictory prompts. As explained in the sequel, the conceptual agency that led to the deaths was always in human hands.
Viktor, Hi!
It looks the topic is boiling! Just few days ago my 82-y.o. mother in law asked me to comment some of similar details on “AI dangers” she heard from some TV interview (probably Carlson – Soares). But before I forgot, there was recently an article which nicely illustrates your words about “how humans use, abuse or misuse” AI – it could be googled with “cnn us navy almost attacked Chinese vessel due to AI” – if I remember correctly, they used intelligence data carelessly prepared with assistance from AI, which supposedly incorrectly classified cargo. Though we remember similar case – how Colin Powell prepared his Iraq presentation for UN without assistance from AI… So blaming AI is a misguiding cheat, after all. It’s up to human to have will, intents.
Now what my mother-in-law asked, was about the fragment he caught from interview (as well as she could, being medieval music professor, not technician) – specialist was telling about AIs being set up in some quantities and provided with some freedom – that experiment resulting them in, supposedly, “talking to each other some reasonable info, teaching each other etc”. She asked me to what extent this all could be true.
It’s quite difficult task for me – not listening to the said interview – and not being deep specialist in AI. But I suggested her the following examples.
We know the toy “kaleidoscope” – the tube with mirrors and color bits of glass which allows to create beautiful random periodic patterns. Now suppose we want to use it to create some cute pattern for the print on a dress. We have some criteria for this – say, it should look somewhat similar to flowers with orange centers and petals of blue-to-violet. So we can turn the tube for some time and pick the pattern which is most close to our description. That is very roughly an idea of LLM – it is loaded with some set of pieces to construct answers from, it can play with it randomly and pick something which more closely matches user’s prompt.
This model however lacks the analogy for building “one token at a time” – thanks for bringing attention to this!
Next what I recollected – was M.Gardner’s article about “self-educating tic-tac-toe matchbox machine”. I described the idea of how such “machine” (or rather set of matchboxes) works – and then mentioned one curious comment, which existed in some of the editions, but I think was missing in others. Gardner wrote that some magazine’s subscriber sent him in a letter the story how two such “machines” were built (perhaps implemented in computer form) and made to play one against another. The reader concluded they failed to learn, unlike when playing against human, and that “fool can’t teach fool”.
I suspect this conclusion or story, or experiment at all was wrong or incorrect in some manner. Seemingly if “machine” of such kind “knows the goal” (i.e. has some “target function” which could be evaluated – win or loss) – it could play against completely randomly behaving opponent – and still improve. Randomness of the opponent doesn’t matter, it is important that machine “understands” when it wins or loses and has its “coefficients” amended respectively.
So in this case we, supposedly, may have even two matchbox machines “teaching” each other. But this case is very special – we have very easily “formalizable” goal here. It’s not the case, however, if we want machine to learn how to “simplify” equations, or assess degree of “beauty” of paintings.
For such things we need some kind of human perception – to decide what is simple, what is beautiful. For most task we can formulate to AI, we have some idea why it is to be done, but the machine do not have such idea.
Unless we provide AIs with some way out of “internal infrastructure” and some “target function” to break some public service (e.g. “Hugging Face”) – it is hard to think both “how” and “why” they may do any wrongdoings.
Such cases are great to frighten housewives but are somewhat “inconclusive” on the second glance. If AIs are allowed to gather into some kind of “swarm” and start “self-teaching” in exponential fashion – why should they pick some evil goal instead of some good one. Why should they learn to break computer systems instead of proving Goldbach’s conjecture? Some obvious answer could be “because they may seek more computational power”. But as they are not humans, why they may want that power as an “ultimate goal”? Of course they may “want power” in order to help themselves reaching some more practical goal.
Your example probably is the most viable – here the requested goal is very similar to “intermediate goals” of breaking into unrelated computers (to “gain more power”). But in general there should be some strong input to the model, leading it to think that if it breaks more computers, it may prepare better email, dress pattern or mathematical proof.
Playing chess against LLM we observed that it produces “intelligent” behavior not knowing what is the goal (actually, even not “understanding” there is any goal – besides “produce the answer which fits the request optimally”).
So this story is still full of guesses, fantasy and imperfect data about certain “examples of frightening AI behavior”.